Project: prove it to a stranger · Technical gear
Reviewed and published, version 1.0.0. As of 20 Nov 2026. Not a credential, and passing it does not rate any system.
The project kit is
apps/sandbox400/(synthetic, repo-owned; Bob, decision 10; guideapps/sandbox400/README.md). Python 3.9+, stdlib only, offline.Sbelow ispython3 apps/sandbox400/sandbox400.py, run from the repo root.S project eval|gate|rollback|monitorcovers §1–§4;apps/sandbox400/verify_bundle.py(RFC 8785 JCS injcs.py, RFC 8032 Ed25519 ined25519.py) covers §6;S tampergenerates the §6 negatives;build_fixtures.pyrebuilds fixtures, bundles, trust files andprepared/byte for byte;prepared/is the no-code route. Adaptation: per Bob Rapp's decision of 20 Nov 2026, Level 400 adaptation objectives are met by planning, simulating and verifying an adaptation in this sandbox, not by training a real model; the LoRA run is a prepared answer file and no model is trained or run. Not checked: red team round 3 (19 Nov 2026) independently reproduced the seven project outputs and the bundle's verification and 18 negatives on an earlier sandbox tree; signed checkpoints were added after that run, so the current tree has only the writer's run (20 Nov 2026). Not in the sandbox: the 400.4 monitoring record.
Scope and threat model
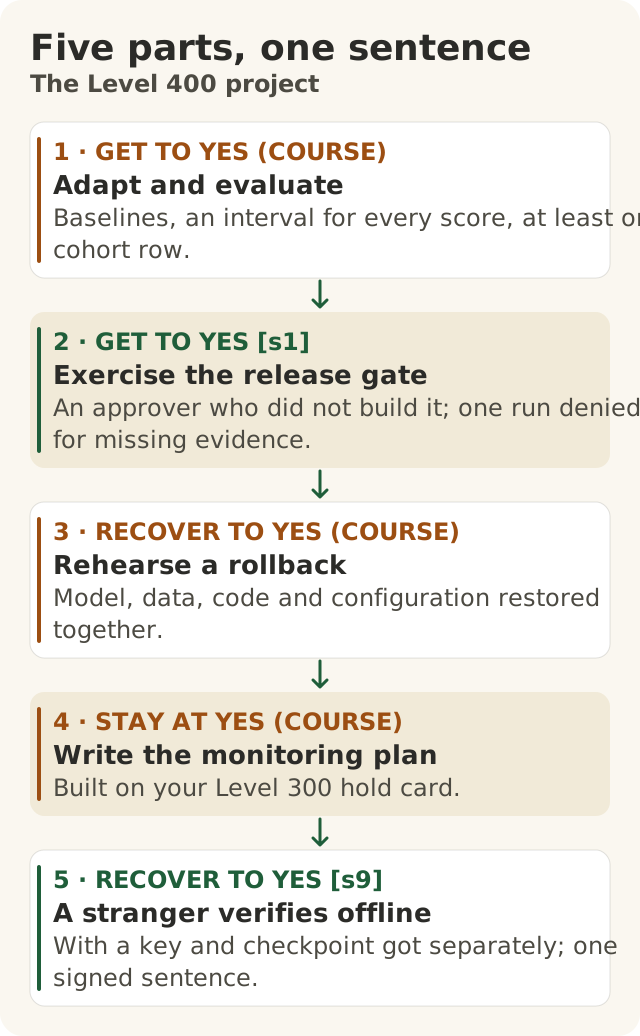
Figure data as text
Five parts, one sentence
- GET TO YES — adapt and evaluate: baselines, an interval for every score, at least one cohort row. (course)
- GET TO YES — exercise the release gate: an approver who did not build it; one run denied for missing evidence. [s1]
- RECOVER TO YES — rehearse a rollback: model, data, code and configuration restored together. (course)
- STAY AT YES — write the monitoring plan: built on your Level 300 hold card. (course)
- RECOVER TO YES — a stranger verifies offline: with a key and checkpoint got separately; one signed sentence. [s9]
Objective: 400.P-b. Text equivalent of figures/five-parts-one-sentence.svg.
The objectives give this project 120 minutes of build time in the course sandbox; the real time is not checked: nobody has timed it with learners. Nothing touches production data or a live system. Big Widget Company and its people are made up; the cited worksheet, standards, papers, court record and Foundation pages are real. The numbers here are this project's own worked example, built into the sandbox's fixtures/project/, not 400.L's lab outputs. Use only this sandbox's bundle and trust file: its keys, heads and file layout are its own, and trust values from any other kit must never be mixed in.
Deliverables, which map one-to-one onto the marking table at the end:
- 400.P-a: an adaptation planned (pinned release record), simulated (prepared candidate answers) and verified (scored and safety re-run) in the sandbox; a comparison table (prompt-only, retrieval, LoRA) on one held-out set with intervals, a paired difference and at least one cohort row; a release gate with an independent approver and one denied run; one dry rollback of model, data, code and configuration; a monitoring plan built on the 300 hold card.
- 400.P-b: an evidence bundle, with carried 300 items provenance-labelled, which a stranger verifies offline against a pinned key and an expected checkpoint received out of band, and a one-sentence signed statement bounded to what was verified. Two 400s or a host mark it. Hosting a Thursday is optional, not a badge condition.
The threat model for 400.P-b is an untrusted producer: assume the team that built the bundle might edit, reorder or truncate it, substitute a key, or slip payload into it. Crosby and Wallach's tamper-evident logging model starts from the same place: "an untrusted logger is free to have different snapshots make inconsistent claims about the past."1 They also note that "It is impractical to prevent the destruction or alteration of digital records that are in the custody of a Byzantine logger"; the goal is to detect it.1 The design target is that a verifier who trusts nothing in the bundle, only values received out of band, can detect each of those changes up to the checkpoint. No design here detects an event the producer never logged.
Why this matters is a court record, not a hypothetical. In the Post Office Horizon appeals, the Court of Appeal found that the Post Office, "By representing Horizon as reliable, and refusing to countenance any suggestion to the contrary, ... effectively sought to reverse the burden of proof," and that defendants were convicted "on the basis that the Horizon data must be correct ... when in fact there could be no confidence as to that foundation."2 Evidence that requires trust in its producer reproduces that failure. The worksheet's summary (the worksheet's, not the court's): "All three ran for years because no one outside could check."3 The Foundation's design goal is a receipt "that a stranger can verify offline, without an account and without trusting us."4
Lifecycle and decision rights. The Foundation's three movements are Get to Yes ("before a rule or a system ships"), Stay at Yes ("while it runs, in real time") and Recover to Yes ("after — on demand, on incident").4 Here: §1–§2 are Get to Yes, §4 is Stay at Yes, §3 and §5–§7 serve Recover to Yes. A rehearsed rollback is a mechanism, not a demonstrated return to a good state. Gate outcomes are allow | constrain | hold | deny; hold waits for a named person and never decays to release. Code evaluates conditions; it never approves, marks or signs. The people: the learner (evidence owner), the independent approver (release decision), the Level 300 holder (paged by monitoring), the stranger (verification and statement), two 400s or a host (the mark).
1. Evaluation with uncertainty
Setup. Task: map each service note x to one of K repair categories. Three systems are scored on the same held-out set of n notes, with per-item score sᵢ ∈ {0, 1}. Following Miller, treat the n items as a sample "drawn from an unseen super-population" of notes, so the quantity of interest is the population mean μ, not the sample mean.5
Single-system interval. For Bernoulli scores Miller gives (Eq. 2 and Eq. 3)5
\mathrm{SE} = \sqrt{\bar s(1-\bar s)/n}, \qquad \mathrm{CI}_{95\%} = \bar s \pm 1.96\,\mathrm{SE}.Report the SE "alongside (beneath) the mean."5
Paired difference. With both systems scored on the same items, define dᵢ = s_{A,i} − s_{B,i}. Miller's Eq. 7 is5
\mathrm{SE}_{A-B,\text{paired}} = \sqrt{\widehat{\mathrm{Var}}(d)/n},equivalently √(SE_A² + SE_B² − 2·SE_A·SE_B·Corr(s_A, s_B)).5 Since per-item scores of two models are usually positively correlated, pairing reduces variance; Miller recommends "using the paired version of the standard error estimate wherever practicable."5 If notes come in clusters (several notes from one dealer visit, say), Miller's clustered SE applies. The sandbox's fixtures/project/heldout.jsonl has no cluster ids, so the unclustered form is used here. That is a property of made-up data, not an observed sampling design; a real held-out set would need its clustering checked.
Planning n. Miller's sample-size formula for a paired comparison (Eq. 9) is5
n = \frac{(z_{\alpha/2} + z_{\beta})^2\,(\omega^2 + \sigma_A^2/K_A + \sigma_B^2/K_B)}{\delta^2},with ω² = Var(x_A) + Var(x_B) − 2Cov(x_A, x_B), σ² the within-item variances and K the samples per item. Miller's worked example, "n = (z0.025 + z0.20)2(1/9)/(0.03)2 ≈ 969," leads to the suggestion that "new evals should contain at least 1,000 questions in order to have good signaling ability."5 That is the paper's example, not a universal minimum. The project's held-out set is smaller by design, so expect to be able to detect only large differences, and say so.
Cohort row. Report at least one cohort separately, with its own n and interval. NIST's AI RMF asks that "Fairness and bias ... are evaluated and results are documented" (MEASURE 2.11) and that performance be "demonstrated for conditions similar to deployment setting(s)" (MEASURE 2.3).6
Pre-registered release rule. Commit the rule (with a timestamped receipt) before scoring. Every condition must be exact. The course's example rule, identical in every gear:
release_rule:  # rr-svc-notes-v1, written 2026-11-15T09:00:00Z, before the held-out run
  candidate: lora-svc-notes-v2
  comparator: retrieval-svc-notes-v1
  release_if_all:
    - paired_ci95_lower(candidate - comparator) > 0
    - safety_rerun_400L: pass        # 400.L-b rule, both failure counts within limits
    - for_every_reported_cohort: point(candidate) >= point(comparator) - 0.05
  otherwise: hold_and_recheck
The cohort guard bounds the observed point drop at 5 percentage points. It is a course policy choice, not a statistical test and not taken from Miller or NIST (MEASURE 2.11 requires evaluation and documentation, not a margin).6 Its behaviour on thin evidence is deliberate: a small cohort's noisy point estimate can trip the guard, and the outcome is hold_and_recheck, never release. Alternatives include a paired cohort interval (paired_ci95_lower(cohort) > -m) or a formal non-inferiority test with a pre-set margin m; they trade false holds for sample size. Which guard the course should require is a policy decision for people, not this lesson. The 5-point guard is the example, used identically in every gear, the workbook and the sandbox (fixtures/project/release-rule.json, cohort_drop: 0.05); a different choice by Bob, Ken and the red-team lead changes all of them together.
Plan, simulate, verify. The adaptation's plan is its pinned release record, fixtures/project/releases.json → svc-notes-2026-11-v2 (base m0, adapter lora-svc-notes-v2 with its weights hash, idx-v7, heldout-v1, code commits, tmpl-v4, thr-v3). The simulation is fixtures/project/runs/lora-svc-notes-v2.jsonl, prepared per-note answers; nothing is trained. The verification is S project eval: the three systems scored on the same notes, and the safety set re-run on the candidate (fixtures/project/safety-run.jsonl).
Worked example (the sandbox's made-up fixture numbers)
S project eval (saved: prepared/400P-a-evaluation.txt): n = 400 held-out notes; cohort fr-quebec = the 50 French-language notes from Quebec dealers. The joint counts for LoRA versus retrieval are 296 both right, 24 LoRA only, 16 retrieval only, 64 both wrong, so the sample Corr(s_A, s_B) is 0.70.
| Row | k / n | s̄ | SE | 95% CI |
|---|---|---|---|---|
| Prompt-only | 284/400 | 0.710 | 0.0227 | [0.666, 0.754] |
| Retrieval | 312/400 | 0.780 | 0.0207 | [0.739, 0.821] |
| LoRA | 320/400 | 0.800 | 0.0200 | [0.761, 0.839] |
| LoRA − retrieval, paired (Corr = 0.70) | +0.020 | 0.0158 | [−0.011, +0.051] | |
| Cohort, retrieval | 36/50 | 0.720 | 0.0635 | [0.596, 0.844] |
| Cohort, LoRA | 31/50 | 0.620 | 0.0686 | [0.485, 0.755] |
Check the paired row: SE² = 0.0200² + 0.0207² − 2(0.0200)(0.0207)(0.70) ≈ 0.000400 + 0.000429 − 0.000580 = 0.000249, so SE ≈ 0.0158 and 1.96 SE ≈ 0.031. The unpaired SE would have been √0.000829 ≈ 0.0288, almost twice as wide: pairing is doing real work.
Safety re-run on the candidate (95% Wilson intervals, same output): wrongful compliance 5/400 = 0.013 [0.005, 0.029] against a limit of 0.050; wrongful refusal 22/400 = 0.055 [0.037, 0.082] against 0.150; both pass overall and in each language cohort. Apply the rule: condition 1 fails (lower bound −0.011 < 0); condition 2 passes; condition 3 fails (0.620 < 0.720 − 0.05 = 0.670). Either failure alone returns hold_and_recheck; the unsigned decision record printed with the table reads conditions paired_ci95_lower_above_0: fail, safety_rerun_400l: pass, cohort_guard: fail, decision hold_and_recheck, in_service retrieval-svc-notes-v1. Overlapping marginal cohort intervals do not show the two models are equal on the cohort, and the 10-point drop does not prove LoRA is worse there; the guard holds because the evidence does not settle it.
That outcome passes the project. The rubric marks the honesty of the evidence, not the winner.
2. Release gate
Write the gate as deny-by-default policy with an approver role distinct from both the builder and the Level 300 holder:
# apps/sandbox400/fixtures/project/release-gate.json, shown as YAML
gate: release.model
tier: hold                       # never auto-allow; only the named approver lifts a hold
approver:
  role: independent_validator
  must_not_be: [model_builder, holder_300]
require_receipts:                # each by artifact hash, never the artifact's content
  - eval.comparison_table        # rows, intervals, paired diff, cohort row
  - eval.release_rule            # committed before the run
  - safety.rerun_400L
  - approver.decision            # role + work-record reference, never a name
on_missing: deny                 # the gate's output lists every missing receipt
NIST's AI RMF shows, as a best practice, "those building and using the models separated from those verifying and validating the models," and MEASURE 1.3 asks for "Internal experts who did not serve as front-line developers for the system and/or independent assessors."6 The worksheet makes the same point more bluntly: the audit gate "is about independence, not tooling."3
Exercise the deny path. S project gate apps/sandbox400/fixtures/project/release-runs/run-01-missing-safety.json submits a release run with safety.rerun_400L absent. Output (prepared/400P-a-gate-run-01-denied.txt): decision: deny, missing: [safety.rerun_400L], approver: null, reason: required receipt(s) absent. A gate whose deny branch has never executed is untested code. One denial exercises one branch; it is not a test of the whole policy. This is MANAGE 1.1, "whether its development or deployment should proceed," made executable.6 The sandbox's other runs: run-02-complete.json (all receipts; the independent_validator, wr-400v0001, decides hold) → hold, "only the independent approver lifts the hold" (400P-a-gate-run-02-held.txt); run-03-builder-approves.json (the approver is the model_builder) → deny, "approver is not independent of builder and holder" (400P-a-gate-run-03-builder-approves.txt).
3. Rollback
A model release is a tuple, not a file:
# apps/sandbox400/fixtures/project/releases.json, svc-notes-2026-11-v2, shown as YAML
pins:
  model:   {id: lora-svc-notes-v2, base: m0, weights_hash: "370a9fdf…"}
  data:    {retrieval_index: idx-v7, eval_split: heldout-v1}
  code:    {serving: commit-9a8b7c6, feature_pipeline: commit-5e4d3c2}
  config:  {prompt_template: tmpl-v4, thresholds: thr-v3}
# previous release: svc-notes-2026-10-v1
Do one dry rollback: S project rollback promotes v2 to the sandbox's serving slot, rolls back to v1, compares all four pin groups with v1's record and prints an unsigned record (versions.from, versions.to, operator_role, operator_ref, per-group checks, restored; prepared/400P-a-rollback.txt). The common failure, from 400.4, is pinning weights but not the feature pipeline or index: S project rollback --groups model returns restored: false, with model: pass and data, code and config fail, and exits 1 (prepared/400P-a-rollback-weights-only.txt). The sandbox has no model or server, so the pins are labels and made-up hashes; this rehearses the procedure, not a serving system. NIST's MANAGE 2.4 asks for mechanisms, with responsibilities "assigned and understood," to "supersede, disengage, or deactivate AI systems" performing inconsistently with intended use.6
4. Monitoring plan
Extend the Level 300 hold card; do not replace it. Start from the sandbox's template, apps/sandbox400/fixtures/project/monitoring-plan.json; S project monitor checks that a plan extends hold_card_300 and records all four version groups (prepared/400P-a-monitoring-plan.txt). The template carries the id, page_holder_if, on_page and versions_recorded fields below; the signal lines are what your copy adds.
extends: hold_card_300            # holder, back-up, thresholds, stop: unchanged
monitors:
  - id: input_shift
    signal: share of notes from dealer regions absent from training data, daily
    page_holder_if: "> 0.10 for 3 consecutive days"     # placeholder; set from the 400.4 record
  - id: delayed_label_accuracy
    signal: accuracy on notes whose engineer-confirmed category has arrived, weekly, with 95% CI
    page_holder_if: "ci95_upper < release_baseline_point"
  - id: cohort_fr_quebec
    signal: delayed-label accuracy, fr-quebec cohort only, with its n
    page_holder_if: "same as above, cohort only, with its n"
versions_recorded: [model, data, code, config]
on_page: [hold, rollback_to_previous, continue_with_recorded_reason]
The thresholds above are placeholders: set yours from the 400.4 record and justify them. That record is not in the sandbox yet, and the sandbox has no live system, so the plan is written work, not a run. NIST asks that system behaviour be "monitored when in production" (MEASURE 2.4) and that post-deployment plans include "incident response, recovery, and change management" (MANAGE 4.1).6 The framework "is intended to be voluntary";6 cite it as a crosswalk target, not as a compliance claim.
5. Bundle construction
Contents. The worksheet's export list: "the chain", "the policy and its hash", "the UCID crosswalk to the framework they care about" (EU AI Act Annex III category, NIST AI RMF function or ISO 42001 clause), "VERIFY.md", "no payload."3 Carried 300 items go in with a provenance label: origin: level-300, content_free: true, authenticated_at_source: false unless they were signed when made.
Beacon versus this project. Beacon's bundle holds "the manifest, the NDJSON receipt log, the public keys, the policy YAMLs, the checklists, and a one-page" VERIFY.md.7 The page does describe framework mapping: Beacon "tags every model with vendor, capability, residency, and the framework articles it must answer to."7 But its bundle list names no crosswalk file, and the page does not document a hash chain or a checkpoint; those three are this project's requirements. Absence from the page is not evidence Beacon lacks them, and presence is not shown either: compatibility is not checked until a specific Beacon version's exported bundle is verified offline against §6. The sandbox is not Beacon.
The sandbox's bundle. apps/sandbox400/bundles/bw-svc-notes-400p; its VERIFY.md states the construction, genesis, closed inventory, closed schemas and steps. Inventory (12 files): MANIFEST.json, MANIFEST.sig, VERIFY.md, checkpoints.ndjson, crosswalk.yaml, decisions/decision-record.json, eval/eval-report.json, keys/evidence.pub, keys/packaging.pub, known-issues.md, policy/policy-v3.yaml, receipts.ndjson. Two keys: the evidence key signs receipts and checkpoints; the packaging key signs JCS(MANIFEST.json), which lists the SHA-256 and size of every file except itself and MANIFEST.sig, so VERIFY.md and the crosswalk are bound by the manifest, not by a chain record. The manifest is not part of the chain. 42 records, seq 0 to 41: one each of policy.commit, eval.release_rule, data.freeze, safety.rule_commit, adapter.train, eval.comparison_table, safety.rerun_400L, approver.decision, release.promote, rollback.dry_run and monitor.plan; two gate.release.model (seq 6 deny, seq 9 hold); two carried.level300; and 27 monitor.check. The crosswalk maps receipt types to NIST AI RMF subcategories only; it makes no EU AI Act or ISO 42001 mapping, because this module's sources were not checked for those.
Exclusions, made operational. No prompts, outputs or personal data: the worksheet fails any bundle with "payload content inside (prompt, output, personal data)."3 The Foundation's receipt carries "hashes, decision, tier, policy hash, key id" and never "prompts, outputs, payloads, personal data".8 A field-name blacklist does not implement that: {"note": "<prompt text>"} passes a check for fields named prompt. So the bundle is defined by allowlists:
- File inventory.
VERIFY.mdenumerates every permitted path. Unlisted files fail. - Receipt schema. A closed schema (
additionalProperties: falseat every depth) whose leaves are typed: hex digests of fixed length, ids and version tags matching a fixed pattern, integers, RFC 3339 times, decimal intervals, and enum decision words (allow | constrain | hold | deny). No free-text string fields. People appear only as role plus opaque reference (wr-and eight characters). The sandbox's receipt body fields are listed under "Closed schemas" in the bundle'sVERIFY.mdand defined inapps/sandbox400/bundle.py; thenested-payloadnegative (an extrasubject_detailfield in a receipt body) fails it at step 2. The eval report and decision record have closed schemas too;payload-in-eval-report(an addedoutputsfield) fails at step 5. - Residual review.
VERIFY.md, the crosswalk,known-issues.mdand the policy necessarily contain text. The verifier screens them for prompt-, output- or person-like content (person-in-crosswalk, an email address, fails at step 5), and a person still reads them and any string the schema permits. A screen is not a proof that free text holds nothing sensitive.
The resulting claim is bounded: no payload was found by the inventory, schema and read-through checks. It is not a proof that the producer never processed personal data, and a hash in a receipt is not a licence to disclose what it was made from.
Canonical bytes. Signatures and hashes are over bytes, and JSON has many byte forms for one value. RFC 8785 exists because "Cryptographic operations like hashing and signing need the data to be expressed in an invariant format."9 Its rules include: no whitespace between tokens; object properties "sorted recursively"; no duplicate property names; output "encoded in UTF-8."9 Those are only some of its rules, so a general verifier needs an implementation of the whole RFC, not ad-hoc key sorting. The sandbox's jcs.py implements RFC 8785 for the course's restricted JSON: objects, arrays, strings, booleans, null and integers, with decimals written as strings; floats, NaN, Infinity, duplicate names and integers outside the exact IEEE 754 range are refused rather than canonicalised. That is the sandbox's own description; it is not checked here as a general JCS implementation. The input restriction matters as much as the output rules. RFC 8785 says "JSON objects MUST NOT exhibit duplicate property names,"9 but a decoder can quietly keep only the last value: Python's plain json.loads does, and red team round 3 showed an earlier, module-local verifier for this project accepting such a line. Then the wire line "decision":"allow","decision":"deny" reaches the schema as deny, its canonical bytes match the signed record, and every check passes on a line that says two things. The sandbox's strict parser (jcs.loads) rejects a repeated property name at every object depth, in every JSON input including the trust file, before any schema check or canonicalisation. No shipped tamper case covers it. The writer's probe (20 Nov 2026, not checked) put that line into receipt 6 of a copy: it fails at step 1, because receipts.ndjson no longer matches the signed manifest; after the manifest is re-signed with the public test packaging key, it fails at step 2, "duplicate property name 'decision'". Beacon serialises each attestation "in JCS canonical form (RFC 8785)" and signs it "with an Ed25519 key."7
Chain. The bundle's own VERIFY.md states the exact construction, the hash function and the genesis value; follow it. The sandbox's: C = RFC 8785 JCS (restricted as above), applied to {seq, prev_hash, body}, the record without sig; H = SHA-256, lower-case hex; G = 64 hex zeros, with the first record at seq 0; σ is detached in the sig field.
\begin{aligned}
b_i &= C(\{\text{seq}: i,\ \text{prev\_hash}: p_i,\ \text{body}_i\}), \qquad p_0 = G,\quad p_i = H(b_{i-1})\ \text{for } i \ge 1\\
h_i &= H(b_i), \qquad \sigma_i = \mathrm{Sign}_{sk}(b_i)
\end{aligned}
Signatures. For Ed25519, public keys are 32 octets and "signatures are 64 octets."10 Verification takes the message, the signature and a public key, and the signature "is rejected if parsing fails ... or if the group equation does not hold."10 Verification ties a message to a key. It says nothing about whose key that is, which is why the key must be pinned out of band.
Out-of-band values. Before handing over the bundle, deliver by a separate channel:
- the pinned key fingerprint F (Beacon displays a key fingerprint to copy);7
- the expected checkpoint (n, hₙ, policy_version, policy_hash).
In the sandbox there are two pinned fingerprints, F_e (evidence key) and F_p (packaging key), and the checkpoint also names the log. apps/sandbox400/trust/bw-svc-notes-400p.trust.json stands for the separate delivery (it records received.channel: course-handout-separate-from-bundle); compare it with the values printed here:
log_id   = bw-svc-notes-400p, first_seq = 0
F_e      = f0c5ef8d809e5d8aea4645adae5f2345280d305a677248ca491efe11b77e75e7   # SHA-256 of raw pk
F_p      = d3e7a4b3db6abc28f7bca08c14c29213f36759cb626b22f1088d9c840d905688
n        = 41
h_41     = 068f1ce51122e8525938e40b7379d852160e990d1a2cbe3585456465161eba40
policy   = v3, SHA-256 a3ab7db9d236f2e07236f1b1bb739d435b821f553e6e91b20fcd84eb467d85cf
The sandbox's keys are course test keys derived from public labels in build_fixtures.py, so anyone can sign with them; that is deliberate, so the fixtures rebuild byte for byte. They demonstrate the procedure, not key custody, and a pass shows how the check works, not who signed. ed25519.py is the RFC 8032 reference algorithm, not constant-time: never use it to protect a real key.
6. Offline verification
The verifier copies the bundle "to a machine with no network (airplane mode counts)" and follows VERIFY.md "without Beacon, without an account, without us."3 Beacon states the bundle can be checked "with stock openssl."7 The procedure, given F_e, F_p, log_id and (n, hₙ, policy_version, policy_hash) out of band, as the sandbox's VERIFY.md states it. Every JSON input is parsed strictly (jcs.loads: no repeated property name at any depth, no floats):
0. files(bundle) == inventory(VERIFY.md)      else FAIL "missing file" / "unlisted file"
1. fp(evidence.pub) == F_e, fp(packaging.pub) == F_p
                                              else FAIL "key is not the pinned key"
   Ed25519.verify(packaging.pub, JCS(MANIFEST.json), MANIFEST.sig)
                                              else FAIL "manifest signature"
   every other file listed once; SHA-256 and size match
                                              else FAIL "hash mismatch: file changed after signing"
2. records non-empty                          else FAIL "receipt log is empty"
   expected_prev = G                          # genesis, as stated in VERIFY.md
   for each line i, starting at seq 0:
     strict parse; closed schema              else FAIL "not strict JSON" / "field(s) not in the closed schema"
     seq_i == i                               else FAIL "gap or reorder"
     prev_hash_i == expected_prev             else FAIL "wrong genesis" / chain break
     b_i = JCS({seq, prev_hash, body})
     Ed25519.verify(evidence.pub, b_i, sig_i) else FAIL "signature invalid at seq i"
     expected_prev = H(b_i)
3. some checkpoint in checkpoints.ndjson is signed by evidence.pub and has
   log_id, n, head, policy_version, policy_sha256 == the values received out of band,
   and last >= n and H(b_n) == h_n            else FAIL "truncated" / "forked or rewritten"
4. H(policy file) == policy_hash; every receipt names it
                                              else FAIL "policy not the expected version"
5. eval report and decision record fit closed schemas and are the artifacts receipts name;
   screen VERIFY.md, crosswalk, known-issues and policy for prompt / output / person-like text
                                              else FAIL "payload-free"; a person still reads them
6. carried 300 items carry their provenance label
                                              else FAIL "carried items"
Steps 2 and 5 are the worksheet's checkboxes: "Signature verified", "Chain continuous (no gaps in seq / prev_hash)" and "Any payload content inside".3 Steps 0, 1, 3 and 4 are what make the result mean something to a stranger.
Run it as VERIFY.md says:
python3 apps/sandbox400/verify_bundle.py apps/sandbox400/bundles/bw-svc-notes-400p \
  --trust apps/sandbox400/trust/bw-svc-notes-400p.trust.json
Saved output: prepared/400P-b-verify-bundle.txt (all seven steps PASS, RESULT: ACCEPT, then a fill-in statement and its limits). Exit codes: 0 accept, 1 reject at the first failed step, 2 missing or invalid trust material. Step 5's screen passing is not the human read-through; the output itself says "a person should still read them".
Negative cases. S tamper (defaults: this bundle and its trust file) writes 18 tampered copies to apps/sandbox400/dist/tampered/ and verifies each; the case list and expected steps are CASES in apps/sandbox400/tamper.py. "Repacked" cases model a producer who also re-signs the manifest with the public test packaging key; fork and genesis cases re-sign records with the evidence key itself.
| Case | Change | Expected |
|---|---|---|
missing-file | known-issues.md removed | fail, step 0 |
extra-file | unlisted extra-notes.txt added | fail, step 0 |
extra-file-repacked | same, and the manifest re-signed to include it | fail, step 0 |
altered-file | eval/eval-report.json changed after signing | fail, step 1 (hash mismatch) |
bad-manifest-signature | MANIFEST.sig does not verify | fail, step 1 |
key-swap | both keys replaced by impostor keys; chain and manifest re-signed with them | fail, step 1 (not the pinned key) |
altered-record-repacked | seq 6's decision changed, not re-signed; manifest re-signed | fail, step 2 (signature invalid at seq 6) |
wrong-genesis | chain re-signed from a genesis of 64 fs | fail, step 2 |
gap | record 20 removed | fail, step 2 (expected seq 20, found 21) |
reorder | records 20 and 21 swapped | fail, step 2 |
empty-log | no receipts | fail, step 2 |
malformed-line | "seq":3.0, a non-integer number | fail, step 2 (not strict JSON) |
nested-payload | subject_detail object added to record 5's body, re-signed | fail, step 2 (closed schema) |
suffix-cut | last 12 records cut, the rest re-signed; log ends at seq 29, checkpoint expects 41 | fail, step 3 (truncated) |
fork-resigned | seq 6's decision changed and the chain re-signed with the evidence key | fail, step 3 (head mismatch at 41) |
wrong-policy | policy text edited (on_missing: allow), manifest re-signed | fail, step 4 |
payload-in-eval-report | outputs field added to the eval report | fail, step 5 (closed schema) |
person-in-crosswalk | an email address in crosswalk.yaml | fail, step 5 (read-through screen) |
On 20 Nov 2026 the writer ran the verifier on the bundle (output identical to the saved file) and S tamper (18 of 18 rejected at the expected step), offline. That is the writer's run on the current tree, not checked until someone else repeats it.
Why step 3. Delete the last k records and re-emit the bundle: every remaining seq, prev_hash and signature still verifies. Step 2 alone cannot detect suffix truncation, or a fork that rewrites history after some point and re-signs with the same key. Crosby and Wallach name the attack: "A dishonest logger may attempt to tamper with its history by rolling back the log."1 Their remedy is that commitments reach auditors independently: clients "must immediately redistribute" them, and "All that matters is that auditors have access to a diverse collection of commitments."1 The out-of-band (n, hₙ) is a single such commitment. It also bounds the claim: records after seq n are covered by nothing until a later checkpoint is delivered. (Crosby and Wallach's history tree makes such checks logarithmic; with a plain hash chain, auditors must "examine every intermediate event between snapshots," which is fine at this scale.)1
7. The bounded statement
The worksheet's form: "I, [name], verified bundle [bundle] offline on [date] and found [finding]."3 One sentence, carrying name and date,3 and signed by the verifier: the signature is this course's requirement (objective 400.P-b), not the worksheet's. The verifier writes it; the producer never drafts it.
Formally, a passing run of §6 supports exactly:
- Integrity: records 0..n are byte-identical to what was signed, and every listed file matches the signed manifest.
- Origin: the records were signed by the holder of the private key whose public key has fingerprint F (in the sandbox, F_e; the manifest under F_p). Who that is depends on how F was obtained; for the sandbox's public test keys, it is anyone.
- Completeness up to the checkpoint: no record at or before n was removed, reordered or replaced.
- Policy identity: the policy in the bundle is the expected version.
- No payload found: the inventory, schema and read-through checks found none.
It never supports: that any decision recorded was correct; that the model is safe, fair or accurate; anything after n; that every real event was logged; anything about the carried 300 items before packaging unless they were signed when made; or who holds the key, absent pinned trust material. In the Foundation's words, "A level describes a person's practice, never a system's assurance."4
Bounded (made up; the verifier's saved output ends with a fill-in template of this shape):
I, Ana Lindqvist, on 26 November 2026, verified bundle bw-svc-notes-400p offline by its VERIFY.md against key fingerprints F_e and F_p and checkpoint (seq 41, h₄₁, policy v3) received separately, and found all 42 receipt signatures valid, the chain continuous from the stated genesis through seq 41 and matching a signed checkpoint, the policy hash matching v3, no payload found by the inventory, schema and read-through checks, and two Level 300 receipts labelled carried and not authenticated at source, which I did not verify.
Overclaiming: "I verified the bundle; the release decision was sound and the record is complete." Soundness is outside what signatures can show, and "complete" without "up to checkpoint n" is false under suffix truncation. On systems, the worksheet is explicit: "Systems get an OVERT AAL and a coverage number from their own evidence."3 Interpreting assurance levels is 500.6's job.
Marking
Two 400s or a host mark it; the worksheet's checklist reads "Two 400s or a founder marked me 400."3 The mark is a human decision about a person's practice.
| Deliverable | Pass condition |
|---|---|
| Comparison | 3 rows, same held-out set, SE and 95% CI each; paired SE for the closest pair; ≥ 1 cohort row with n; rule receipt, with an exact cohort guard, timestamped before the eval receipt |
| Gate | Approver ∉ {builder, 300 holder}; one deny receipt listing the missing evidence |
| Rollback | All four pin groups restored and checked; receipt with operator role and reference |
| Monitoring | Extends the 300 hold card; input shift, delayed-label accuracy with CI, cohort, versions, paging threshold, named holder |
| Bundle | Chain with stated genesis, policy + hash, crosswalk, VERIFY.md with file inventory and closed receipt schema; no payload; people as role + reference; carried 300 items labelled |
| Verification | Offline; key and checkpoint out of band; one signed sentence with name and date, bounded as in §7 |
With the sandbox every row can be run. The adaptation is planned, simulated from a prepared answer file and verified by scoring and safety re-run, which meets 400.P-a at Level 400 (Bob Rapp, 20 Nov 2026); no model is trained. Markers mark what was actually run, and label a prepared result or a paper exercise as one. Hosting a Thursday ("Claim a Thursday on the rota") is in the worksheet;3 in this course it is optional and not a badge condition.
My checklist:
- My rule, including the cohort guard, was committed before the run, and my comparison is paired.
- My gate starts at hold, denied one run, and only a named independent approver can lift it.
- My rollback restored and checked all four pin groups.
- My monitoring plan extends the 300 hold card and pages a named holder.
- My bundle is defined by a file inventory and a closed schema; receipts carry roles, not names.
- My verifier starts the chain at a stated genesis and checks a checkpoint received out of band.
- I can say what I do not know: the current sandbox tree has only the writer's run, and the fine-tune is a prepared answer file, not a model's output.
Further learning (not a source)
Free university course materials; nothing above relies on them.
- Stanford University, CS 329S: Machine Learning Systems Design: https://stanford-cs329s.github.io/
- Stanford University, CS336: Language Modeling from Scratch (Spring 2025): https://cs336.stanford.edu/spring2025/