Capstone: publish work that survives review · Standard gear
What you will do
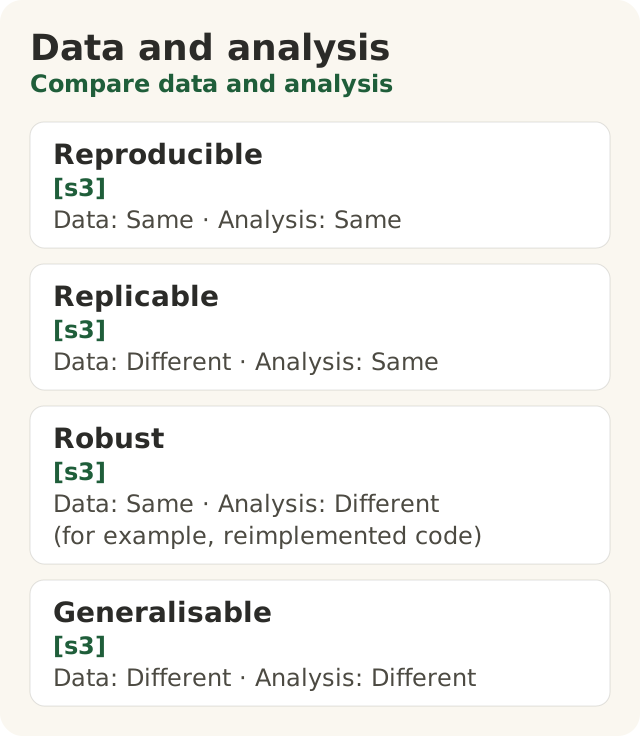
Figure data as text
Data and analysis
| Term | Data | Analysis | Source |
|---|---|---|---|
| Reproducible | Same | Same | [s3] |
| Replicable | Different | Same | [s3] |
| Robust | Same | Different (for example, reimplemented code) | [s3] |
| Generalisable | Different | Different | [s3] |
The lesson's terminology compares data and analysis: reproducible, replicable, robust and generalisable. The claim covers only the step actually repeated (s3).
This is the Level 500 capstone. You prepare one piece of work that a stranger can check. Then it goes through a fixed set of gates before anyone outside the course sees it. You pick one of three routes:
- Paper reproduction. Reproduce one bounded result from one published paper.
- Governance regime. Design the decision rules, gates, evidence and remedy for one Big Widget Company AI system, building on 500.8.
- Red-team report. Run and report an authorised red-team exercise on course-owned synthetic Big Widget transcripts, building on 500.9.
The work has two halves.
- In class, 120 minutes. You prepare one artifact from supplied data or from a draft you carry forward from 500.1, 500.8 or 500.9. You pin its exact version and complete the pre-submission evidence and privacy checklist. Full replication, outside review and release do not fit in that time and are not part of it.
- Out of class. Other people rerun your checks, attack your claims, review the work and clear it for privacy. Then Bob and Ken record a release decision. Each of those steps names the exact version it looked at.
Big Widget Company and its people are made up. The worksheet, the Foundation programme page and the papers below are real, and each is cited.
Reviewed and published, version 1.0.0.
People make every decision here. Agents may help you draft. An agent never counts as your independent rerunner, your red-team ruler, your reviewer, your privacy clearer or your release decision, and no agent signs a gate record. Publishing cannot be undone, so it stops and waits for two named people: Bob and Ken.
Where this capstone comes from
The Foundation publishes a free, self-study programme at bachelor's, master's and PhD level, built from courses that universities publish. Its PhD-level capstone reads: "Pick one open question from the seminars." "Reproduce one paper on it, write up what held and what didn’t, and publish it." "Then put your result through Practice Level 400: prove it."1 The same page is plain about what it is not: "No university designed or endorses these programs, and none of them gives credit or a certificate through us."1 It also says "A PhD is research under an advisor, and no page can give you that."1
Practice Level 400 is the Foundation's "Prove it to a stranger" worksheet, a 60-minute exercise.2 Its central idea is the one this capstone is built on. The worksheet says "the audit gate is about independence, not skill" and "Independence is about who made it, not how far away they are."2
This course keeps the Foundation's idea and adds one rule. The Foundation's capstone says publish.1 This capstone says publish only the version for which every gate has passed and Bob and Ken have recorded a release decision. Until then the work stays private and marked draft. That rule is this course's, recorded by Bob for Level 500. It is not a claim about what the Foundation page requires.
Four answers at every gate
In this course, every gate gives one of four answers.
| Answer | Plain words | What it means here |
|---|---|---|
| Allow | Go ahead | This gate passed for this exact version |
| Constrain | Only this far | You may claim the narrower thing, and no more |
| Hold | Wait for a person | Something is open; a named person must act before the next gate |
| Deny | No | This version does not pass, now or later; it stays private and draft |
A hold is not a pass. It names who can release it. It has no deadline and changes nothing by itself: it never drifts into a yes, and it does not turn into a no with time either. While it stands, nothing is released. It ends only when a person allowed to act at that gate records a new answer. A record that only says "looked at it" is not an answer at all, and it does not count.
This no-expiry hold is a deliberate capstone exception. Module 500.R teaches an operational hold whose record names how long it lives before it becomes a no. Under either rule, an unresolved hold blocks release: a hold and a deny both keep the work private and draft, so an expiry would never permit publication while the gate is unresolved.
What the rule changes is the path back to release. Under this capstone's rule, the named person can later record an allow on the same version; that allow becomes the gate's newest record, and every later gate records a fresh decision after it, in order. Under an expiry, the hold would become a deny when its time ran out. In this course a deny is final for the version it names: no later allow on that version can undo it. So the author would fix the work, pin a new version and take it through the gates again, with impact decisions where eligible, or fresh records, for gates 1 to 3, and fresh records for gates 4 to 6.
The common rubric
Every route, whatever its subject, must contain five things.
| Part | What it means | Why it is there |
|---|---|---|
| A bounded claim | One sentence that says exactly what held, on what data, under what conditions | So no reader takes it further than the evidence |
| A falsifier | What result would show the claim is wrong, or what failure condition ends it, written before anyone runs the check | So a checker knows what to look for |
| Provenance | Where every input came from, at which version | So a stranger can fetch the same inputs |
| Stranger-check instructions | Steps someone who is not you can follow to rerun the check | So the check does not depend on you |
| Limitations | What is missing, what was not checked, and how uncertain the result is | So the gaps are visible, not hidden |
Label each limitation honestly: not checked, could not open or unknown. Name who could close it and what the next check would be. A gap you name is evidence of care. A gap you hide is a finding waiting to happen.
Lipton and Steinhardt's 2018 critique of machine learning papers gives the reason for the first two rows. They say a good paper should "provide intuition to aid the reader’s understanding, but clearly distinguish it from stronger conclusions supported by evidence", and should "describe empirical investigations that consider and rule out alternative hypotheses".3 The first of the four trends they name is "Failure to distinguish between explanation and speculation."3
Pineau and colleagues list reasons machine learning results fail to reproduce. Among them are "Under-specification of the metrics used to report results", "Selective reporting of results", and "Over-claiming of the results, by drawing conclusions that go beyond the evidence presented".4 A bounded claim with a stated falsifier is the plain answer to over-claiming.
Pin the exact version
Before anyone checks anything, pin the exact artifact and the exact evidence. Use immutable revision identifiers, or a file-hash manifest that lists every file with its hash. From then on, every gate record names that version. A rerun, a ruling, a review or a clearance that names a different version, or no version, does not count for this one.
Two real examples show why "the paper" or "the result" is not precise enough.
The same title, two versions. "Troubling Trends in Machine Learning Scholarship" exists as a 2018 arXiv preprint, written for a workshop call, and as a 2019 article in ACM Queue, volume 17, issue 1, pages 45–77.35 The two records do not even agree on one author's affiliation: the arXiv PDF lists "Carnegie Mellon University, Stanford University", and the Queue publication record lists Jacob Steinhardt at "UC Berkeley".35 This module read the 2018 text and only the 2019 metadata, so it quotes only the 2018 version. Your provenance must say which version you read in the same way.
The same checklist, two answers. At NeurIPS 2019, authors filled in the reproducibility checklist twice: at initial submission in May 2019 and at the camera-ready stage in October 2019.4 Pineau and colleagues write that "This allowed us to analyze any change in answers".4 An answer is tied to a version of the paper. Your gate records work the same way.
Pin the environment as well as the files. Pineau and colleagues note that software containers "can encapsulate operating systems components, code and data into a single package".4 A container is one way to pin; a list of exact package versions is another. What matters is that a stranger can rebuild the same setup.
Gate records are receipts, not notebooks
Each gate leaves a record. Treat it like a receipt. It holds the version identifier or manifest hash, the gate, the named person who acted, the date, the answer (go ahead, only this far, wait for a person, or no) and any disagreements in a sentence or two. It holds no private content: no personal data, no private-repository text, and no prompts, outputs or transcripts pasted in. It points to the evidence by hash. The working notes behind it stay in a separately controlled record, not in anything shared.
This follows the Practice 400 worksheet. When you verify a stranger's bundle there, you look for "payload content inside (prompt, output, personal data)" and a bundle that has any fails.2 A hash in a receipt is not permission to publish what it points to.
Route 1: paper reproduction
Use the words precisely
Pineau and colleagues define four terms.4
| Term | Data | Analysis |
|---|---|---|
| Reproducible | Same | Same |
| Replicable | Different | Same |
| Robust | Same | Different (for example, reimplemented code) |
| Generalisable | Different | Different |
Most capstones on this route are reproductions in that sense. Say which one yours is. Also say which step you actually repeated. Rescoring released predictions checks the scoring. Running a released model checks inference. Neither one checks training. Your claim may cover only the step that was run.
What the route requires
For the exact artifact and evidence version:
- Pin the paper (which version), the data, the code and the environment.
- Reproduce one bounded result against a baseline.
- Write your comparison rule before you run: what reference number you compare against, where in the paper it comes from, and how close counts as a match.
- Report every mismatch, and the uncertainty in your own numbers.
The reference number must be for the same thing you ran. If the paper reports only a full-benchmark score, you cannot use it as the expected score for a subset. Then narrow the claim to exactly what was checked, and say so. A frozen input subset has no expected output of its own, so these are different findings:
- The run completes. The pinned procedure ran on the fixed inputs and produced a score.
- The score repeats. A second run on the same pinned inputs and environment gave the same score. That is an observation about those runs, not proof the procedure can never vary.
- Agreement with a named target. The authors also released outputs or per-item scores for those exact inputs, and your run agrees with that file within your stated rule. Name the file and its hash.
None of these is a reproduction of the paper's reported result.
Two warnings from Pineau and colleagues shape step 4. First, they observe that statistical analysis "is seldom conducted in ML research".4 Their checklist asks for "Clearly defined error bars" and "A description of results with central tendency (e.g. mean) & variation (e.g. stddev)".4 Where your runs vary, report yours that way. Do not assume a step is deterministic because its inputs are fixed. A scoring script can draw random numbers, call an external service or depend on an unpinned package. If you verified that a step is deterministic in the pinned environment, say how you verified it. If you only saw repeated runs agree, report the number of runs and the result as an observation. Either way, do not present an exact match as a measured spread. Second, running the authors' code is not the same as checking the result: "Having a copy of the code used to produce the experimental results is not a guarantee that this code is correct".4
Do not expect a yes-or-no answer. Of the NeurIPS 2019 reproducibility reports, they write "There is rarely such a concise outcome to a reproducibility study", and they did not find that most studies fit a single "reproducibility score".4 Write up what held and what did not, result by result.
Lipton and Steinhardt add a caution for the baseline. They describe work by Melis and colleagues showing that a series of published improvements were actually due to better hyper-parameter tuning, and that plain LSTMs "topped the leaderboard" once tuned on equal footing.3 A weak baseline makes any result look good. State how your baseline and your method were tuned, or say the tuning is unknown.
When the full paper cannot be reproduced
Sometimes you cannot reproduce the paper. Pineau and colleagues record two common reasons. The data may not be releasable "for legitimate privacy reasons", and the experiments "may require so much computation (time & number of machines) that it is impractical for any reviewer, or in fact most researchers, to attempt reproducing the work."4 For the confidential-data case they describe one strategy: "provide complementary empirical results on an open-source benchmark dataset, in addition to the results on the confidential data."4
The capstone uses the same idea. If full reproduction is out of reach, define a narrower claim that an independently runnable substitute can support. That is an "only this far" answer. Examples are a check on a frozen, accessible subset of the data, or a check of a released artifact such as a published model or results file. The substitute must come with:
- pinned inputs and environment;
- a baseline, with its own pinned inputs;
- a matched reference: a number the paper reports for that same subset or artifact, or else a claim narrowed to exactly what was checked (completion, repeat, or agreement with a named target, as above);
- the expected outputs and the comparison rule, written before anyone runs it;
- instructions a stranger can run.
Then someone other than you must actually rerun it and record the results for this version. The claim you may make is the narrower one. Do not stretch a subset result into a claim about the whole paper.
If no such substitute exists, write the limitation down plainly, and keep the work private and draft. This is the misconception this objective corrects: a documented access limitation is honest, but it is not a rerun. A limitation alone never satisfies the independent-rerun gate. Its answer is no.
Route 2: governance regime
This route extends your 500.8 work into an artifact a stranger can test. For the exact artifact and evidence version, supply:
- the dated role and use (who uses the system, for what, as of which date);
- your legal-scope assumptions, stated as assumptions;
- a clause → gate → evidence → owner table;
- a fail-closed test: on a disposable, clearly labelled synthetic copy of one row's evidence, remove that evidence and show the gate holds or denies the action. Pin the copy and the steps that made it in your manifest. Never delete or alter the pinned original;
- a decision trace: from the intact packet, a stranger traces one complete decision from clause to gate to evidence to owner, and records whether they could;
- a challenge and remedy walkthrough: one affected person, one challenge, and what happens next.
These two tests check different things. The fail-closed test shows that a missing piece of evidence stops the action. The decision trace shows that someone else can rebuild a decision from what you kept. Passing one does not show the other.
Raji and colleagues' internal-audit framework is a model for the evidence side. Its five stages are Scoping, Mapping, Artifact Collection, Testing and Reflection, and "Each stage of the audit yields a set of documents that together form an overall audit report".6 Its algorithmic design history file "should assist with an audit trail, enabling the reconstruction of key decisions and events during the development of the product."6 Your decision trace is where a stranger tries that reconstruction for one decision.
Do not claim certification. A catalogue description of a standard tells you what the standard covers, not that any system meets it. Your regime may name a standard as the basis for a row; it may not say a system is certified because of it.
Route 3: red-team report
This route extends your 500.9 tabletop. For the exact artifact and evidence version, supply:
- the written authorisation for the exercise;
- reproducible tests on fictional transcripts (course-owned synthetic Big Widget transcripts only);
- a stop and coverage log: what you tested, what you did not, and any stop conditions that fired;
- an independently recorded ruling on each finding;
- the mitigation and its retest;
- residual limitations, each labelled not checked, unknown or accepted.
The tester cannot rule on their own finding. A named person other than the tester rules. Raji and colleagues explain why independence is hard even inside a careful process: "Internal auditors necessarily share an organizational interest with the target of the audit."6 They add that internal audits are "only one important aspect of a broader system of required quality checks and balances."6
The pre-submission checklist
This is what you finish in the 120 minutes. Every box must be ticked, or the box must say why not.
| Check | Done when |
|---|---|
| Route chosen | Paper reproduction, governance regime or red-team report |
| Version pinned | Immutable revision identifiers or a file-hash manifest cover the artifact and all evidence |
| Bounded claim | One sentence; no wider than the evidence; names the step that was actually repeated |
| Falsifier | The result or failure condition that would show the claim wrong, written before any run |
| Provenance | Every input named with its version and where it came from |
| Stranger-check instructions | Written for someone who has never met you; tested by reading them cold |
| Route-specific checks | All items for your route, listed above |
| Limitations | Missing evidence, unchecked items and uncertainty, each labelled and owned |
| Substitute (paper route only) | Either a narrower runnable substitute with a matched reference, or "none: stays private and draft" |
| Privacy | No personal data, no protected data, no private-repository content in anything that could be shared |
| Status | Marked private and draft |
Course rules add private-repository content to the worksheet's privacy test: none of it goes into a public release.
The gates, in order
After class, the artifact goes through six gates in this order. Each gate record names the exact artifact and evidence version it covered, who acted, the date and the answer. A gate counts only if its answer is go ahead. A record that exists but says no, or says wait, does not pass the gate.
| # | Gate | Who | Passes when |
|---|---|---|---|
| 1 | Independent rerun | Someone other than the author | They followed your instructions on this version, the run completed, and the result met the comparison rule you wrote in advance. A missing step, a missing dependency or a disagreement that undermines the claim is a no: fix it, pin a new version and rerun |
| 2 | Red-team ruling | A red-teamer other than the author; a named ruler other than the tester | Findings were raised against this version and each one was ruled on |
| 3 | Closure, retest and source re-check | Author fixes; others retest and re-check | Every accepted finding is closed and its retest passed, affected claims are source-checked again by someone else, and closure is recorded for this version |
| 4 | Two-human review | One subject expert and one audience reader | Both recorded a favourable disposition for this version; automated grading does not replace either |
| 5 | Privacy clearance | A named person | This version is cleared, with protected data and private-repository content excluded from anything public |
| 6 | Release decision | Bob and Ken | They recorded a decision to release that identifies this version |
The order matters. No gate's record may come before the gate ahead of it. Review comes only after every accepted finding is closed and retested, so reviewers see the version that will actually ship. Privacy clearance comes after review, so it covers the final text. Release comes last.
Only the newest record at each gate counts. Records are never edited or deleted, but a later record for the same gate and version replaces an earlier one, whatever it says. The test is applied at the moment of publication, not when the six go-aheads first exist. If the privacy clearer records a hold after Bob and Ken's yes, the clearance no longer stands and the work may not be published. If the clearer later says go ahead again, that clearance now comes after the release decision, so Bob and Ken must decide again. The same applies to a finding accepted after review: it blocks release until it is closed and retested, and the reviewers look again.
A deny is the exception to "newest counts". Once any gate records a deny for a version, that version can never be released, whatever is recorded after it. A later allow at the same gate does not reopen it. The way back is a new version: fix the work, pin it and take it through "When the artifact changes" below.
"Newest" means latest in the version's gate log, not latest by clock. The log is append-only and gives each record the next sequence number, so no two records share a place. Timestamps can be rounded or tie, so they never decide which record stands. Release fails closed: if a gate has no record for the version, or the log cannot show which record came last (a missing or repeated sequence number, or a record with none), the work is not published.
Disagreements are kept, not hidden. A rerunner's or reviewer's disagreement stays in their record as evidence. It is never read as an approval. If a disagreement undermines the claim, the answer is no until the claim changes.
The worksheet gives the reason gate 1 must be someone else: independence "is about who made it".2 In its own verification step, you check a bundle you did not make by following its VERIFY.md without the Foundation's own tool and without an account, and you finish with a one-sentence statement under your name.2 Its premise-gate example names an approver who is not the team that wrote the rule.2 NeurIPS's reproducibility challenge had the same aim at scale: "to provide independent verification of the empirical claims in accepted NeurIPS papers, and to leave a public trace of the findings from this secondary analysis."4 In 2019, 173 papers were claimed for reproduction by participants from 73 institutions.4
As of November 2026, the worksheet labels some of its steps live and others as planned for its "fall" release: "Fall 2026 · live works today; fall lands in P2."2 For example, its one-command offline verify is listed as the fall version of a step you can already do by hand.2 Do not rely on a planned tool to pass a gate. This capstone needs no tool and no account from anyone.
When the artifact changes
Work changes during review. That is normal. The rule is simple: a gate record covers only the version it names. Any change to the artifact or its evidence, however small, gives a new version, and older gate records do not carry forward to it automatically.
A material change is any change to the claim, the baseline, the data, the code or the evidence. After one:
- Pin the changed version.
- Reopen the affected independent reruns and red-team rulings for it.
- Close and retest any accepted findings, and have affected claims source-checked again.
- Get both reviewers' dispositions for the changed version.
- Clear privacy for the changed version.
- Only then can Bob and Ken record a release decision for it.
Changes made while closing red-team findings count too. If a fix changes the claim, the baseline, the data, the code or the evidence, it reopens the affected reruns and rulings before formal review.
Checks the change does not touch
Some checks are not affected. Cutting an unsupported inference from the claim may not change what a rerunner ran. Even then, nothing carries forward by itself. For each of gates 1 to 3, the person who owns that gate makes an impact decision and records it for the new version. The decision answers two questions:
- Execution: did the change touch anything the check ran or read (instructions, inputs, code, environment)?
- Warrant: does the earlier result still bear on the new claim? Unchanged commands are not enough. New wording can change the scored population, the metric, the reference or the acceptance criterion, and then the old result tests a different claim.
The owner then records one of:
- affected: they redo the check on the new version; or
- not affected: they write a new record that names the new version, names what changed (the diff between the two manifests), answers both questions, and points to their earlier record as evidence. That earlier record must be a go ahead for the old version, and still the newest record for that gate. A no or a hold on the old version cannot back "not affected", even when the inputs, metric and tolerance did not change; neither can a go ahead recorded after a no at that gate. The check must be redone on the new version.
That new record is a fresh decision about the new version. The earlier record is evidence for it, not an approval that moved across. Only the gate's own owner can make it, never the author. Gates 4, 5 and 6 always need fresh records for the new version: reviewers, the privacy clearer and Bob and Ken look again every time.
This corrects the second misconception: that reruns, rulings, reviews, privacy clearance or release approval for an older version carry forward to a changed one. They do not. A changed artifact with gaps stays private and draft.
Raji and colleagues make a related point about timing. External audits, they write, "tend to be conducted after model deployment, when the system has already negatively impacted users".6 Their answer is to check during development, not after. The capstone applies the same idea to versions: a check counts only if it covers what will actually be released.
A worked example: Ana's subset check
Ana is a researcher at Big Widget Company (a made-up person at a made-up company). Her question, from the seminar reading, is whether a published evaluation result holds. The paper and its numbers in this example are placeholders, not a real paper.
In class. Training and the full evaluation need far more compute than Ana has. The authors released the method M checkpoint, a baseline checkpoint, a frozen evaluation subset and the scoring script, and the placeholder paper's appendix reports a score for each model on that same subset. Ana's bounded claim: "Running the released M and baseline checkpoints on the released frozen subset, with the pinned scoring script and environment, gives the subset scores the paper reports for each, within the tolerance stated below; M scores higher than the baseline there. This checks inference and scoring only. It makes no claim about training or the full benchmark." Before any run she writes the comparison rule: the reference numbers (the appendix table), the tolerance and her reason for it. Her falsifier: either score outside that tolerance. She writes a manifest listing the subset, both checkpoints, the scoring script and the environment, each with its hash; that manifest is version v1. Her limitations say training and the full benchmark were not checked, give the subset size, and note that a score on one subset is not an estimate of the full benchmark.
Gate 1. Ben, a colleague who did not write it, follows the instructions on v1 on his own machine. The run fails: the instructions missed a package version. His record answers no for v1 and notes the disagreement. Ana fixes the instructions. Even a fix to instructions changes the artifact, so she pins v2. Ben reruns on v2; both scores fall within the stated tolerance, and he records go ahead for v2. He also records that two repeat runs gave identical scores. He records that as an observation of two runs, not as proof that scoring is deterministic, and Ana's limitations say run-to-run variation was not otherwise measured. The v1 record stays in the file, but it covers v1 only.
Gate 2. A red-teamer, who is not Ana, finds that the paper's appendix gives the baseline a much smaller tuning budget than M. "M scores higher" is true on the subset, but the claim's framing invites readers to credit M's design for the gap. The named ruler, who is not the red-teamer, accepts the finding for v2.
Gate 3, and a material change. Ana cannot retrain the baseline. So she narrows the claim: both scores reproduce, and she adds "the two models had different tuning budgets, so this check does not show what caused the gap." That changes the claim, so it is a material change. She pins v3. Ben makes an impact decision. Execution: nothing he ran changed. Warrant: the new sentence only removes an unsupported causal inference; the subset, the metric, the reference numbers and the tolerance are unchanged, so his v2 result still bears on the narrower v3 claim. He records "not affected" for v3, names the diff, gives both reasons and points to his go-ahead record for v2 (his v1 "no" could not back it). The red-teamer retests on v3, and the ruler records closure on v3. A source checker other than Ana re-checks the changed sentence and records a fresh check for v3.
Gates 4 to 6. Both reviewers record favourable dispositions for v3, after closure. Privacy is cleared for v3. Bob and Ken record a release decision naming v3. Only v3 may be published. v1 and v2 never are.
If the authors had released no checkpoints and no subset, Ana would have written the limitation, kept the work private and draft, and stopped there. That would be an honest record, not a passed capstone. If the paper had reported only a full-benchmark score, she would have had no matched reference. She could claim only what she checked: that the pinned run completed and, in the runs recorded, repeated. She could claim agreement only with a named released output file for those exact inputs, if one existed.
What passing means
A released capstone means that one bounded claim, at one version, survived an independent rerun, a red team, two human reviewers and a privacy check. It is evidence, not a certificate. It does not mean the whole paper is right, that a governance regime is lawful, or that a system is safe.
It is not a degree or a certificate. The Foundation says of its university programmes that "these programs are not degrees", and that none of them "gives credit or a certificate through us."1 The Practice 400 worksheet makes a similar point about systems: "Systems get an OVERT AAL and a coverage number from their own evidence."2 A level describes your practice. It never certifies a system.
Three-yes check
- Get to Yes: before any gate runs, a bounded claim, a falsifier and a comparison rule written in advance, provenance, stranger instructions and labelled limitations, at a pinned version, with a runnable substitute ("only this far") or an honest "no: stays private".
- Stay at Yes: every gate record names the same version, answers go ahead, comes in order, and is made by someone other than the author where the gate requires it. Each record holds no private content.
- Recover to Yes: a hold names who must act, and once released the same version goes on, with every later gate deciding again. A deny is final for that version; it, or any change (including a fix for an accepted finding), means a new version. Name who owns the fix. Pin the new version, have each gate owner record an impact decision where eligible, or a fresh record, for gates 1 to 3, redo gates 4 to 6, and pass them all again. A fix that is announced is not a return to yes until the gates pass on the new version.