Grounding it in your documents · Standard gear
Reviewed and published, version 1.0.0. As of 18 Nov 2026. Not a credential. Research results are dated in the text; treat them as "as of" the date given.
You will be able to:
- explain what grounding changes (the model answers from documents you supply or a tool retrieves) and what it does not fix (200.3-a);
- ask for answers that quote and point to the passage they used, and check each quote against the source (200.3-b);
- spot when a grounded answer goes wrong because the documents contradict each other, are out of date or are missing; name who owns fixing them; and know when to escalate a wrong answer whose documents look right (200.3-c).
Big idea: grounding puts the right pages in front of the model. It does not make the model read them well, and it cannot make wrong pages right. Check the quote. Fix the documents. Escalate the rest.
Lesson 100.6 called this an open-book tool. This lesson is about using one well at work: what to ask for, what to check, and who to call when it goes wrong. Big Widget Company and all its documents in this lesson are made up.
1. What grounding changes
An answer is grounded when the model is asked to answer from documents put in front of it, instead of only from what it learned in training. There are two common ways this happens:
- You supply the document. You attach a file or paste in a page and ask a question about it.
- A tool retrieves it. A search step looks through a set of documents, picks the passages that seem to fit your question, and hands them to the model with your question. This is retrieval-augmented generation (RAG).
The researchers who named RAG in 2020 built it because a model's stored knowledge has limits: they wrote that showing where an answer came from ("provenance") and updating what the model knows were still open research problems.1 In one small test about world leaders, they swapped in a newer document index, and the model's answers changed to match the newer documents without retraining the model.1 Those were research tests on Wikipedia, not tests on any company's documents.
So grounding changes two things that matter at work:
- The answer can use your documents. The model can work from Big Widget's own returns policy, not a guess about returns policies in general.
- The answer can follow your updates. When the policy page changes, a grounded tool can use the new version.
2. What grounding does not fix
The misconception this corrects: "If I attach the document, the answer comes from the document." It may not. Three things can still go wrong.
The model may not use all of what it is given. In a 2023 study, researchers gave language models a question plus 10, 20 or 30 documents, exactly one of which held the answer, and moved that one document around.2 The models did best when the answer was near the beginning or the end of what they were given, and worse when it was in the middle.2 For one model, GPT-3.5-Turbo, accuracy could drop by more than 20% depending on where the answer sat.2 In some of the 20- and 30-document tests, it did worse than when it was given no documents at all (56.1% correct with no documents).2 Models built to take longer inputs were not necessarily better at using them.2 These were the models of 2023; newer models were not tested in that paper. The lesson that lasts is this: being given a document is not the same as using it.
The model can go beyond the document. NIST, the US standards agency, calls the risk of "confidently stated but erroneous or false content" confabulation.3 It says confabulations "also include generated outputs that diverge from the prompts or other input".3 A grounded answer can quote the right policy and then add a detail the policy does not contain.
The documents themselves can be wrong. If the policy page is out of date, or two pages disagree, a model that reads them faithfully will still give a wrong answer. Section 5 covers this.
At Big Widget Company: three answers about returns. Lee in dealer support attaches Big Widget's returns policy page (made up for this lesson). It says: "This policy covers all returns, including returns from dealers. Unused parts may be returned within 30 days of delivery with the original invoice. Custom-built widgets cannot be returned." A dealer asks whether they can return an unused part after 40 days. Lee gets three answers from three tries:
| Answer | Supported by the page? |
|---|---|
| "No. Unused parts must be returned within 30 days of delivery." | Yes. The page says this. |
| "No, but after 30 days you can return it for store credit with a 15% restocking fee." | No; it only sounds like it. Store credit and the fee are not on the page. They sound like a returns policy, which is why they are easy to miss. |
| "Yes, as long as you have the original invoice." | No. It takes one true condition from the page and drops the 30-day limit. |
All three sound like they came from the policy. Only one did. The way to tell is the next section.
3. Ask for the quote and where it is
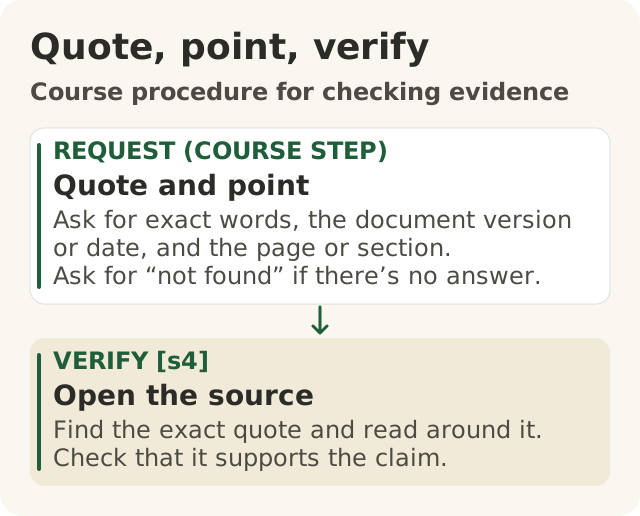
Figure data as text
Quote, point, verify
- Quote and point (course step) — ask for exact words, the document version or date, and the page or section. Ask for “not found” if there’s no answer.
- Open the source — find the exact quote and read around it. Check that it supports the claim. [s4]
Objective: 200.3-b. Text equivalent of figures/quote-point-verify.svg.
A grounded answer is only as useful as your ability to check it. So ask for answers you can check. In this course, that means asking the tool, every time, to:
- Quote the exact words from the document that support each claim, in quotation marks;
- Point to where they are: the document's name, its version or date, and the section or page;
- Say "not found" when the documents do not answer the question, instead of answering anyway.
For example: "Answer only from the attached returns policy. For each claim, quote the sentence that supports it and give the section. If the policy does not answer the question, say 'not in the policy'."
This is the course's practice, built on the open problem the RAG authors named: showing where an answer came from.1 Asking does not make it so. The model can still get a quote or a section wrong, which is why you check.
4. Check each quote against the source
The misconception this corrects: "A citation in the answer means the source says it." It does not. NIST warns that AI outputs "may also include confabulated logic or citations that purport to justify or explain the system's answer, which may further mislead humans into inappropriately trusting the system's output".3 A citation is a claim about the source, and it needs checking like any other claim.
NIST's profile suggests that organizations "Review and verify sources and citations in GAI system outputs" (action MS-2.5-003).3 For one person checking one answer, that comes down to four steps:
- Open the real source. Not the quote in the answer: the document itself, the version your company publishes now.
- Find the quote. Is it there, word for word? A quote you cannot find is a red flag, whatever else the answer gets right.
- Read around it. Does the sentence before or after change its meaning, such as an exception, a date range, or "except for custom-built widgets"?
- Match claim to quote. For each claim in the answer, does the quoted passage actually say it? An answer can quote a real sentence and then claim something that sentence does not support.
Step 4 catches most problems. In the returns example, an answer might quote the 30-day sentence correctly and then add the 15% restocking fee. The quote is real. The fee is not in it. Strike the claim the passage does not support, and do not pass it on.
The research in section 2 is a reason to check every claim, not only the first: a model may use the start or end of a long document well and the middle badly.2
How much checking? This lesson teaches how to check one answer. How much checking a task needs, from spot checks to checking every answer, is Lesson 200.4.
5. When the documents are the problem
The misconception this corrects: "Wrong answers are always the model's fault, never the documents'." A grounded tool can only be as right as what it reads. Three document problems turn up again and again:
- Contradiction. Two published documents say different things. The tool may quote either, and both quotes will check out.
- Out of date. The tool reads last year's version, or an old copy that was never removed.
- Missing. Nothing covers the question. The tool should say "not found", as section 3 asked. If it answers anyway, it has filled the gap. That is two problems: a gap in the documents, and a tool that did not say "not found".
NIST describes high-integrity information as information that "can be linked to the original source(s) with appropriate evidence" and that "creates reasonable expectations about when its validity may expire".3 The course's practice, which goes beyond NIST's wording: every document a grounded tool reads should have a source, a named owner and a date after which someone checks it again. NIST also suggests verifying that retrieval-augmented generation data "is grounded" (MS-2.5-005) and tracking changes to datasets, such as deletions and corrections, that affect where content came from (MG-4.1-006).3
The anchor case: Moffatt v. Air Canada (2024)
The case carries the customer's name, as court cases do. The lesson does not need it, so the story below says "the customer".
In November 2022, after a family death, a customer asked the chatbot on Air Canada's website about bereavement fares: the reduced fares for people travelling because a family member has died.4 The chatbot said they could ask for the reduced fare after travelling, within 90 days of the date the ticket was issued.4 The same answer linked to Air Canada's own "Bereavement travel" page, which said the policy did not apply to travel that had already happened.4 Two parts of one website gave two different answers.
The customer brought a small claim at British Columbia's Civil Resolution Tribunal.4 Air Canada argued that it could not be held liable for what its chatbot said, as if the chatbot were a separate entity responsible for its own actions.4 In a decision dated 14 February 2024, the tribunal called this a "remarkable submission".4 It held that the chatbot is part of Air Canada's website, and that Air Canada is responsible for all the information on its website, whether it comes from a static page or a chatbot.4 The tribunal did not expect the customer to double-check the chatbot against another part of the site, and found that relying on it was reasonable.4 It found negligent misrepresentation and ordered Air Canada to pay the customer C$650.88 in damages, plus interest and tribunal fees.4
What it means for grounding:
- The company owns what it publishes, both versions. The policy page and the chatbot were both Air Canada's. The tribunal held the airline responsible for the information on its website, chatbot included.4 So the job of reconciling what a company publishes belongs to the company, not to the customer and not to the chatbot.
- Customers are not the checkers. The tribunal did not expect the customer to cross-check one part of the website against another.4 The checking you learned in section 4 is for staff before an answer goes out, not for customers after.
What it does not show. The decision does not describe how the chatbot produced its answer: whether it retrieved a document, which one, or why it said what it said.4 So we cannot say whether this was a document problem or a model problem. On that question the honest answer is "unknown", and we do not guess. It is also one decision of one provincial tribunal on one small claim.4
6. Who fixes it, and when to escalate
When a grounded answer is wrong, first ask: do the documents it used look right?
| What you find | Whose fault, most likely | Who owns the fix | What you do |
|---|---|---|---|
| Two published documents disagree | The documents | The owner of each document, reconciled by whoever owns that topic | Report both documents to their owners; do not pick one yourself for customers |
| The quoted document is out of date | The documents | The document owner, and whoever runs the document set the tool reads | Report it; use the current version; ask for the old one to be removed |
| No document covers the question | The documents; and the tool, if it answered instead of saying "not found" | The owner of that topic for the gap; the tool's owner if it answered anyway | Report the gap; if the tool answered anyway, escalate that too. Give no answer until the gap is filled or a person decides |
| The documents look right, but the answer is wrong | Not clear | The tool's owner | Escalate: send the question, the answer, the quotes and the real source to the tool's owner |
"Owner" means a named person, not "the team" or "IT". If you do not know who owns a document or the tool, that is the first thing to find out. Write "owner unknown" and ask your manager; do not guess.
The last row is the one people skip. If the documents are right and the answer is still wrong, you cannot fix it by editing a page. Do not just try again until you get a better answer and move on: the next person may not try again. Escalate it, so the people who run the tool can record it and look into it. NIST suggests organizations "record and track GAI system reported errors, near-misses, and negative impacts" (MG-4.3-002) and make sure the people monitoring reported issues can "promptly escalate issues for response" (MG-4.1-007).3
Finding out why a grounded answer went wrong (did the search step fetch the wrong passage, or did the model misuse the right one?) is Level 300. At Level 200, your job is to notice, report the documents to their owners, and escalate the rest.
At Big Widget Company: Lee in dealer support, two weeks later. In this made-up company, Ana owns the returns policy and Tom runs the dealer assistant.
- A document problem. The assistant tells a dealer that unused parts can be returned within 60 days, and quotes a "Dealer returns" page that says so. Lee checks: the quote is real. But the main returns policy says it "covers all returns, including returns from dealers", and gives 30 days. Lee reads around both quotes, as in section 4, for anything that settles it: an exception, a date range, a line saying one page replaces the other. There is none. Two current Big Widget pages give two rules for the same returns. Lee cannot tell which rule is meant, and choosing is not Lee's job. Lee tells the dealer the answer is being checked, and reports both pages to Ana. Big Widget, like Air Canada, owns both pages.
- An escalation. The assistant says custom-built widgets can be returned within 30 days, and quotes the 30-day sentence. Lee checks: the policy is current and clear that custom-built widgets cannot be returned. The documents look right; the answer is not. Lee does not answer from it, and escalates the question, the answer, the quote and the policy to Tom.
7. The three yeses for grounded answers
The Foundation names three moves: Get to Yes before something runs, Stay at Yes while it runs, and Recover to Yes after something goes wrong.5 A Foundation gate gives one of four answers: "go ahead · only this far · wait for a person · no".5 What follows is this course's application of them to grounded answers, not a quotation.
- Get to Yes (before you rely on the tool). Which documents does it read? Is each one current, with a named owner? Who owns the tool, and how do you reach them? Does your prompt ask for quotes, places and "not found"? Where you do not know, write "not checked" or "unknown" and name who you will ask.
- Stay at Yes (each answer). Check every answer that matters, every time, with the four steps in section 4. Each checked answer gets one of the four gate answers. Go ahead: every claim checks out. Only this far: strike the claims the quotes do not support, such as the 15% fee, and use the rest. Wait for a person: the documents disagree, are out of date or are missing, or the answer is wrong over documents that look right. Name the person: in Lee's case, Ana for the pages and Tom for the tool. No: the answer cannot be checked at all. One good answer is not a standing approval for the next one.
- Recover to Yes (when a wrong answer got out). Say a dealer was told 60 days and acted on it. Stop using that answer and tell Ana. Once Ana has decided which rule stands and fixed the pages, put it right for the dealer. Then ask the same question again and check the new answer before you say "recovered". A pulled answer is stopped, not yet recovered.
Keep the evidence, not the secrets. Lee's escalation to Tom carries the question, the answer, the quotes and the real source. That is a work record. It belongs in Big Widget's own ticket or work files, under the company's rules for customer data. The Foundation's signed receipt is a different thing: it "holds no private content".5 It never carries "prompts, outputs, payloads, personal data".6 So the dealer's details and the assistant's answer stay in the work record, not in a receipt.
8. Bringing it together
My checklist for a grounded answer:
- I know which documents the answer came from, and that they are the current versions. Where I do not know, I wrote "not checked" and named who I will ask.
- Each claim has a quote and a place, and I have found each quote in the real source.
- Each quote supports the claim it is attached to. I struck anything that is not supported.
- If documents disagree, are out of date or are missing, I reported them to their named owner.
- If the tool answered when it should have said "not found", or the documents look right and the answer is still wrong, I escalated it to the tool's owner.
- My notes stay in the work record. Nothing private goes into a receipt.
Words to know: grounding, grounded answer, retrieval, retrieval-augmented generation (RAG), confabulation, citation, quote, provenance, document owner, tool owner, escalate, gate, Get to Yes, Stay at Yes, Recover to Yes, receipt.
Further learning (optional, not part of this lesson):
- University of Washington, Carl T. Bergstrom and Jevin D. West, Modern-Day Oracles or Bullshit Machines? No-code lessons on why fluent, confident text is not evidence: <https://thebullshitmachines.com/> (free for personal and non-commercial educational use; see the authors' terms).
- Optional, technical (graduate computer science): Carnegie Mellon University, 11-667 Large Language Models: Methods and Applications (Fall 2025), whose schedule includes retrieval-augmented generation: <https://2025.cmu-llms.org/schedule/>; and Stanford University, CS224N, lecture "Agents, Tool Use, and RAG": <https://web.stanford.edu/class/cs224n/>.