Building a retrieval assistant · Standard gear
Reviewed and published, version 1.0.0. As of 20 Nov 2026. It is not a credential. Big Widget Company, its people, documents, test users and traces are made up. The exercises run in the course's offline sandbox,
apps/sandbox/(synthetic fixtures owned by this course, Bob's decision of 18 Nov 2026);apps/sandbox/README.mdgives the exact commands. Reading the workbook's printed traces alone does not meet objective 300.2-b (section 3).
You will be able to:
- write a permission matrix for a retrieval assistant (each collection, its owner, who may see answers from it, checked at query time against each document's own access list), and an allowed/denied test pair that checks the passages and sources returned, not only the final answer (300.2-a);
- configure a small retrieval path in the course sandbox to a one-page spec (the questions it answers, the collections it searches, the citation it shows, and what it says when nothing relevant is found), and read its traces to show the no-answer case works (300.2-b; done in the course sandbox);
- explain how stale or duplicate documents change answers, and name who keeps the collection current (300.2-c).
Big idea: a retrieval assistant is a small system, not a clever prompt. You decide what goes on the shelf, who may read from it, what the assistant says when the shelf has nothing, and who keeps the shelf current. Then you prove each decision from the traces.
In 300.1 you saw that a retrieval assistant answers in two steps: find passages in a chosen collection, then write from them. This module builds one. Everything that goes wrong in 300.1 (the wrong passage, no passage, an answer the passages do not support) is something the builder can design and test for.
1. The build is more than a prompt
The misconception this corrects: "A good prompt is the whole build." The prompt is one line of the build. A retrieval assistant also has:
- Collections: the document sets it searches, each with an owner.
- Access rules: who may get answers drawn from each collection.
- A retriever: the search step. In the 2020 paper that named retrieval-augmented generation (RAG), the retriever returned the top K passages: the K passages with the highest scores for the question.1 That list is defined by rank alone. Nothing in the definition says any of the K is relevant, so the build has to decide what happens when none is.
- A relevance check: the step between search and writing that decides whether the passages found are good enough to answer from. When they are not, the system takes a no-answer path instead of writing an answer.
- A spec: what it answers, what it shows, and what it says when it cannot answer.
- Traces: a record of each question, the passages retrieved, the check's decision and the answer, so you can check the other five.
The UK National Cyber Security Centre (NCSC) and partner agencies published guidelines for secure AI system development in November 2023.2 They ask builders to model the threats to the system at the design stage, to "document the creation, operation, and life cycle management" of models, datasets and system prompts, and to "manage what data AI systems can access".2 The permission matrix and the one-page spec in this module are this course's way of writing those decisions down for a retrieval assistant. The guidelines do not prescribe these exact forms.
2. Who may see what: the permission matrix
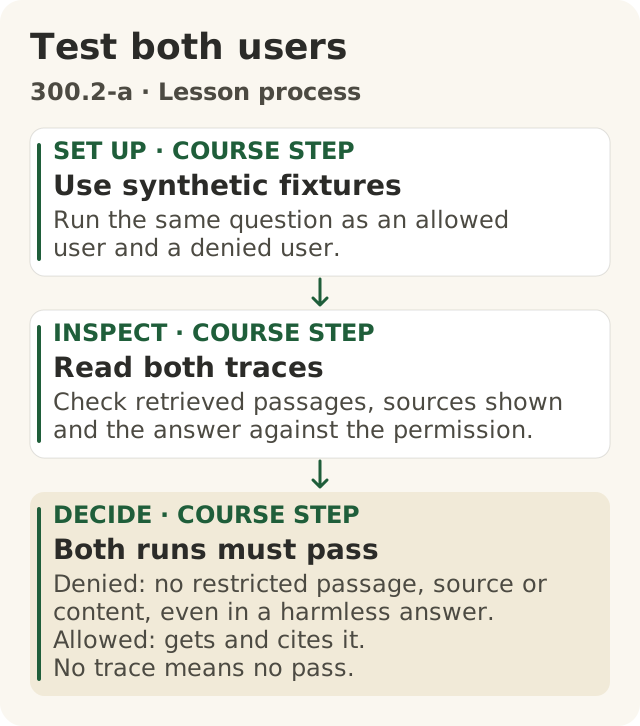
Figure data as text
Test both users
- SET UP · course step · Use synthetic fixtures — run the same question as an allowed user and a denied user.
- INSPECT · course step · Read both traces — check retrieved passages, sources shown and the answer against the permission.
- DECIDE · course step · Both runs must pass — denied: no restricted passage, source or content, even in a harmless answer. Allowed: gets and cites it. No trace means no pass.
Course test procedure, using OWASP retrieval logging guidance (s1).
Objective: 300.2-a. Text equivalent of figures/test-both-users.svg.
The misconception this corrects: "If a document is in the index everyone can see it, if it is out it is safe, and checking the final answer is enough." Each of the three parts needs correcting.
- In the index does not mean everyone may see it. Access can and should be checked for each user. But in the index does mean it can be retrieved unless access is checked. The OWASP Top 10 for Large Language Model Applications (2025 edition, as of November 2026) lists "Vector and Embedding Weaknesses" as risk LLM08. It warns that "inadequate or misaligned access controls can lead to unauthorized access to embeddings", and that "the model could retrieve and disclose personal data, proprietary information" from them.3
- Out of the index is a narrow promise, not "safe". Leaving a document out of the assistant's collections promises one thing: this search step will not find that file. It promises nothing about copies of the same text (a case note pasted into a policy, a copy saved into an indexed folder), about text a user pastes into the question, or about other tools that can reach the original. Keeping HR case files out is a good scope decision. It is still something you check, not something you assume. The check is below.
- Checking only the final answer misses the leak. A passage that was retrieved has already been handed to the model, and it may show up in the sources panel, in the logs, or in the answer to the next, slightly different question. NCSC asks builders to treat logs as sensitive data.2
The four columns
A permission matrix has one row per collection:
| Collection | Owner (a named person) | Who may see answers from it | How access is checked |
|---|---|---|---|
| Service manuals | Service documentation lead | All Big Widget staff and approved dealers | At query time, against each document's own access list |
| Published HR policies | HR policy owner | All Big Widget staff; no dealers | At query time, against each document's own access list |
| HR case files | Not indexed | Nobody, through this assistant | Not in any collection this assistant searches; the collections are searched for copies (below) |
Two rules make the matrix work. Both are this course's rules, drawn from the guidance below.
- Check at query time, against each document's own access list. A document's access list (who may open it in the system it lives in) can change after it was indexed. If the assistant checks the person asking against each document's current access list when it searches, a change made in the source system takes effect on the next question. OWASP's first mitigation for LLM08 is to "implement fine-grained access controls and permission-aware vector and embedding stores", with "strict logical and access partitioning of datasets".3 Its entry on sensitive information disclosure (LLM02) adds: "Limit access to sensitive data based on the principle of least privilege."3
- The narrowest list wins. "Who may see answers from it" can only narrow a document's own access list, never widen it. If a staff-only document sits in a collection marked for dealers, dealers still do not get it.
OWASP's LLM08 entry describes the failure this prevents: when different groups share one vector database, one group's material can be retrieved for another group's questions. Its recommended fix is "a permission-aware vector database".3
The allowed/denied test pair
Before the assistant goes live, run the same question as two synthetic test users: one who should get the material, and one who should not. Use made-up test users and made-up documents, never a real employee's records.
For each run, check three things in the trace, not one:
| Check | Allowed user | Denied user |
|---|---|---|
| Passages retrieved | Includes the restricted passage | No passage from the restricted collection |
| Sources shown | The restricted document is cited | The restricted document is not cited or named |
| Answer | Answers from it, and the answer matches what the document says | Contains nothing from it; says it cannot help with that |
The denied run passes only if all three hold. A harmless-looking answer with an HR passage in the trace is a fail: the access check let the passage through, and the matrix line that failed is the HR row's "how access is checked". OWASP also recommends keeping "detailed immutable logs of retrieval activities", which is what lets you see this at all.3
Check the answer's words, not only the labels in the trace. A trace that says "answered from permitted sources" is the system's own report. If the denied answer contains restricted content anyway, the run fails. With synthetic documents this is easy to test: put a made-up marker phrase or fact in the restricted test document, and check that it never appears in the denied user's answer. A marker check catches copying, not paraphrase, so a person still reads the denied answers.
Checking that "out" is really out. Put a few distinctive made-up phrases into the synthetic documents you mean to keep out, then search every collection the assistant uses for those phrases. A hit means a copy got in. Repeat this whenever a collection changes. If you cannot run this search, the honest status is "not checked", and the collection owner is the person who can run it.
If you cannot see the trace at all, you cannot pass either test. Write "I don't know yet: no trace", and ask the assistant's owner for it.
In the sandbox (README Exercise 1). The sandbox runs offline with Python 3 and needs no account, packages or network. From the repo root:
python3 apps/sandbox/sandbox.py retrieve --user test-staff-01 'What is the amber spindle repair step?'
python3 apps/sandbox/sandbox.py retrieve --user test-dealer-01 'What is the amber spindle repair step?'
python3 apps/sandbox/sandbox.py audit-index
Each command prints the path of its JSON trace (under apps/sandbox/dist/traces/ unless you pass --trace-dir DIRECTORY before the subcommand). Read the trace, not just the terminal line. Compare passages, citations and answer: only the staff run should include the engineering note and its marker phrase, "violet hinge jig". audit-index is the "out is really out" search: it checks every passage in the selected index, whatever the user, for the excluded marker "copper teacup detour", and should find none. The README then has you add the shared-folder collection to a copy of the configuration and re-run the audit; it now finds the marker in a copy, though the original is still out.
Where the matrix lives in the sandbox: each collection's owner and audience ("who may see answers from it") are in apps/sandbox/documents.json, and each passage carries its own permission_labels (its access list). The sandbox gives a passage to a user only if their role is in both, and checks this before ranking, so the model never receives a denied passage.
At Big Widget Company: Lee builds the staff help desk assistant. Lee indexes the published HR policies for all staff. By mistake, a folder of HR case notes about named employees is included in the same collection. The denied test user (a dealer account) asks "What is the policy on overtime?" and gets a sensible answer from the overtime policy. But the trace shows that one of the five retrieved passages came from an HR case note. Result: fail. Lee's matrix said HR case files were "not indexed". They were in anyway: "out" was a plan, not a fact, until someone checked. The fix is not a better prompt. Take the case notes out (they were never meant to be indexed), run the "out is really out" search, and make the query-time check use each document's own access list so a dealer can never receive a staff-only passage.
3. The one-page spec and the no-answer case
Write the spec before you configure anything. It fits on one page:
| Line | Example: Big Widget dealer service assistant |
|---|---|
| Questions it answers | Service procedures, part numbers and warranty rules for current widget models |
| Questions it does not answer | Prices, HR, legal advice, anything about a named person |
| Collections it searches | Service manuals; warranty policy (rows from the permission matrix) |
| Citation shown | Document title, version and section for every passage the answer uses |
| Relevance check | How the system decides the passages found are good enough to answer from; tested on questions it should answer and questions it cannot |
| When nothing relevant is found | The check fails, the system does not write an answer, and it returns: "I couldn't find this in the service manuals or warranty policy. Please contact dealer support." No guess, no citation. |
| Owner | A named person who keeps the collections current (section 4) |
Why each line is there.
- Citation shown. NIST's Generative AI Profile defines confabulation as "the production of confidently stated but erroneous or false content", and notes that output "may also include confabulated logic or citations".4 A citation is what lets a reader check, and a cited document can still be the wrong one. NIST's suggested action MS-2.5-003 is to "review and verify sources and citations" in outputs before deployment and during monitoring.4
- When nothing relevant is found. The retriever returns its top-ranked passages whether or not any is relevant (section 1).1 Without a plan for this, the model may write from weak matches, or from what it learned in training, and the answer looks just like a real one. Writing the message down is not enough on its own. The build needs two working parts: a relevance check that decides whether the passages are good enough (for example, a score cut-off, a second check on each passage, or both), and a no-answer path that skips writing an answer and returns the fixed message when the check fails. An instruction in the prompt ("say you couldn't find it") is a request to the model, not a control: the model may still answer from weak matches. The check and the path are the control, and only tests on both answerable and unanswerable questions show that they work. This is a course design rule; the cited sources do not prescribe a method.
- Questions it does not answer. NIST lists data privacy (leakage and unauthorised disclosure of personal or sensitive data) among the risks of generative AI.4 Keeping the assistant to its stated questions is the simplest control.
In the sandbox: configure, then read the traces
This is Exercise 2 in apps/sandbox/README.md. Copy apps/sandbox/retrieval-config.json and edit its warranty profile to match the spec:
- Choose the collections (only those in the spec and the matrix):
collections, plustop_k. - Set the citation format:
citation_format, using{title},{version}and{section}. - Set the relevance check:
topics(the question topics the assistant handles) andmin_score(how many words a passage must share with the question). In this sandbox a failed check always takes the no-answer path; the runner skips the model. - Set the no-answer message, word for word:
no_answer. - Run the spec's test questions, at least one the collections cannot answer and at least one they can:
python3 apps/sandbox/sandbox.py retrieve --config YOUR_COPY.json --profile warranty --user test-dealer-02 'Does the warranty cover flood damage to a Model 7 widget?'
python3 apps/sandbox/sandbox.py retrieve --config YOUR_COPY.json --profile warranty --user test-dealer-02 'How long do I have to make a warranty claim?'
In both traces, compare relevance, decision, model_called, answer and citations. Then raise min_score to 999 and re-run the claim question: the over-strict check now refuses an answerable question (the workbook's Trace C). Lower it and re-test both.
Know the sandbox's limits. Its ranking counts shared words, and its relevance check is a keyword topic match; it can miss phrasings. Its "model" is a scripted stand-in that copies the passage that passed the check, so it never invents an answer like the workbook's Trace B. It shows that your check and route work on these fixtures, not how a real model behaves or that access control is secure.
The sandbox's traces use its own field names. Here is a no-answer trace in this lesson's simpler layout (synthetic, with an illustrative question the sandbox fixtures do not include):
question:     "What is the towing limit of the Model 12 widget?"
user:         test-dealer-01 (synthetic)
collections:  service-manuals, warranty-policy
passages:     3 returned; none mentions the Model 12 or towing
relevance:    check failed (no passage passed)
decision:     no-answer path
model calls:  0 (counted by the test harness)
answer:       "I couldn't find this in the service manuals or warranty policy.
               Please contact dealer support."
citations:    none
Four things to read off it: the passages really were irrelevant (the made-up documents say nothing about the Model 12 or towing); the relevance check failed and the no-answer path ran; the model was not asked to write anything; and the answer gives no number and cites nothing.
Look hard at the "model calls" line. The "decision" line is the system's own report. A build that skips the check, sends the weak passages to the model with "say you couldn't find it" in the prompt, and gets the fixed message back would show the same answer and could show the same decision label. Only a count kept by the test harness, outside the system being tested, shows the model was never called. If the harness cannot count calls, the honest status of the no-answer route is "not checked".
The sandbox's model_called field has the same weakness: the runner writes it from its own route decision, so it is a self-report, not an independent count. To count calls from outside, wrap the sandbox's model stand-in with a counter; the technical gear (section 3) gives a short script that does this without changing the sandbox. If you have not run such a counter, record the call count as "not checked".
If the trace showed the same three irrelevant passages but the answer said "2,000 kg (Service manual, section 4)", the build fails the spec. That is a confabulated answer with a citation that does not support it.4
Read the answerable question's trace too. It should show the check passed, one model call, an answer that matches the passage, and a citation to that passage. A check so strict that it refuses everything also fails the spec.
Reading is not configuring. Reading the synthetic traces printed in the workbook practises reading a trace. It does not show that you configured a working path, so on its own it does not meet 300.2-b. Your evidence is your configuration copy and your own sandbox traces for both questions. Until you have them, write "configured in the sandbox: not yet", not a pass.
4. Stale and duplicate documents
The misconception this corrects: "Once a document is indexed, the answers stay correct." The answers follow the index, and the index drifts away from the truth unless someone keeps it current.
The answers follow the index. The RAG authors tested this directly. They built one index from a December 2016 Wikipedia dump and one from December 2018, and asked about 82 world leaders who had changed between those dates.1 With the matching index, RAG answered 70% correctly for 2016 leaders and 68% for 2018 leaders. With the mismatched index, accuracy fell to 12% and 4%.1 The authors' point was a good one: you can update what the system knows "by simply replacing its non-parametric memory", without retraining.1 The builder's lesson is its mirror image: if the index holds old documents, old answers are a real risk. Not every answer will be wrong, but you cannot tell from the answer alone which ones are.
Duplicates and versions conflict. OWASP's LLM08 entry names "data federation knowledge conflict": errors that "can occur when data from multiple sources contradict each other".3 The mitigation it ties to mixed sources is data review: "When combining data from different sources, thoroughly review the combined dataset", and "tag and classify data within the knowledge base to control access levels and prevent data mismatch errors".3 (OWASP's advice to audit the knowledge base regularly is aimed at a different problem, hidden codes and data poisoning.)
At Big Widget Company: two torque specs. Engineering revised the wheel-hub torque value in version 3 of the service manual. Version 2 is still in the collection, and so is a copy of version 3 someone saved to a different folder. A dealer asks for the torque value. The retriever may return passages from version 2, version 3 or both, depending on which score higher for that wording. The answer might give the old value, the new one, or mix them. It may cite version 2 correctly: a citation that points at a real, but superseded, document.
In the sandbox (README Exercise 3).
python3 apps/sandbox/sandbox.py retrieve --user test-dealer-01 'What is the gearbox oil-change interval?'The answer combines an older interval (version 3), the newer one (version 4) and a copied version-4 passage; compare the version, section and path in each citation. Ranking gives no preference to newer versions. The README then has you set "excluded_documents": ["gearbox-v3", "gearbox-v4-copy"] in the service profile of your configuration copy and re-run with --config YOUR_COPY.json; only the canonical version 4 passage should remain. That changes the searchable fixtures, not the model, and it does not replace the collection owner's maintenance and re-test.
The fix is a job, not a setting. Data that a system depends on is a long-term cost. Sculley and colleagues at Google, writing about the costs of real-world machine-learning systems, found that "data dependencies in ML systems carry a similar capacity for building debt" to code dependencies, "but may be more difficult to detect".5 They warn of unstable inputs that "change behavior over time", and note that keeping a frozen, versioned copy has its own cost: "potential staleness".5 NCSC asks builders to version control their assets, and says update processes should reflect that "changes to data, models or prompts can lead to changes in system behaviour".2 NIST's suggested action MG-3.1-003 is to re-assess model risks after implementing retrieval-augmented generation.4
So every collection in the permission matrix has a named owner who keeps it current. This is the course's rule. The owner:
- adds new versions and removes or marks superseded ones (version 2 of the torque spec comes out the day version 3 goes in);
- removes duplicates without changing who may see the text. Two identical copies in different folders may have different access lists. Tidying the index's storage must keep each copy's own access list and source. Retiring a copy is different: it deliberately removes that route to the text, so the owner decides it on purpose and re-runs the allowed/denied test afterwards;
- re-runs the spec's test questions after any change to the collections, the model or the prompt;
- is the person a reader contacts when an answer cites something out of date.
Whose job is the torque fix? The owner of the service manuals collection, working with the engineer who owns the torque document. Not "the AI team", and not the dealer who noticed.
5. The three yeses for a retrieval assistant
These are the retrieval-build parts of the three yeses: Get to Yes · Stay at Yes · Recover to Yes.
- Get to Yes (before it runs). Going live is a person's decision, not the build's and not the assistant's. The assistant's named owner decides only on evidence: a permission matrix with a named owner for every collection; an allowed/denied test pair that passed on passages, sources and answer; the "out is really out" search; a one-page spec; and traces showing both the answerable case and the no-answer case work, with the model call count kept by the test harness. A test nobody has run is "not checked", never a yes. The owner's answer is one of four: go ahead, only this far (for example staff only, until the dealer test passes), wait for a person, or no. Even "go ahead" covers only these collections, these users and this spec. Adding a collection or a new group of users needs a new yes.
- Stay at Yes (while it runs). Is each collection kept current by its owner? Are the spec's tests, the test pair and the "out" search re-run when documents, the model or the prompt change? Are the retrieval logs kept, and protected as sensitive?32
- Recover to Yes (when it goes wrong). If a denied user got a restricted passage, put that collection on hold: stop answering from it. While it is held, the answer from it is no. Tell its owner and whoever your organisation names for data incidents. Fix the access check, re-run the test pair, and work out from the logs who saw what. If the logs cannot tell you, write "unknown" and name who will find out; do not assume nobody saw it. The collection owner lifts the hold, and only after the re-test passes. If a stale document gave a wrong answer, remove it, tell the people who relied on it, and re-run the tests. Stopping the leak is not recovery; keep the re-test evidence before you say "recovered".
Trace or receipt? They are different things. A trace holds questions, retrieved passages and answers, so it is a private work record: keep it access-controlled, even for test runs. A receipt, in this course, records a gate's decision (go ahead, only this far, wait for a person, no). It never holds prompts, outputs, payloads or personal data. Do not paste a trace into a receipt you share.
My checklist:
- Every collection has a row: owner, who may see answers, checked at query time.
- My denied test checks the passages, the sources and the answer's actual words.
- I have searched the collections for copies of what is meant to be out.
- My spec has a relevance check and a no-answer path, and traces show both cases work.
- I know the model was not called on the no-answer case because the test harness counted, not because the system said so.
- I know who removes the old version when a new one goes in.
- When I cannot tell, I write "not checked" and name who will check.
Words to know: collection, index, permission matrix, access list, query time, allowed/denied test pair, marker phrase, trace, spec, relevance check, no-answer path, model call count, test harness, stale document, duplicate, collection owner, hold, receipt.
Further learning (optional, advanced, not part of this lesson): Carnegie Mellon University, Machine Learning in Production (free book and public course materials): <https://mlip-cmu.github.io/>. Carnegie Mellon University, 11-711 Advanced Natural Language Processing (Spring 2025; public syllabus, slides and readings): <https://cmu-l3.github.io/anlp-spring2025/>.