Gen AI in your role (role tracks) · Standard gear
Reviewed and published, version 1.0.0. As of 18 November 2026. Big Widget Company and its people are made up. Every real organization and case below is real and cited. The task card, the four kinds of check, the track rows, the "drafts or acts" sort and the gate answers are this course's own practice, not a law or a standard.
What this module does
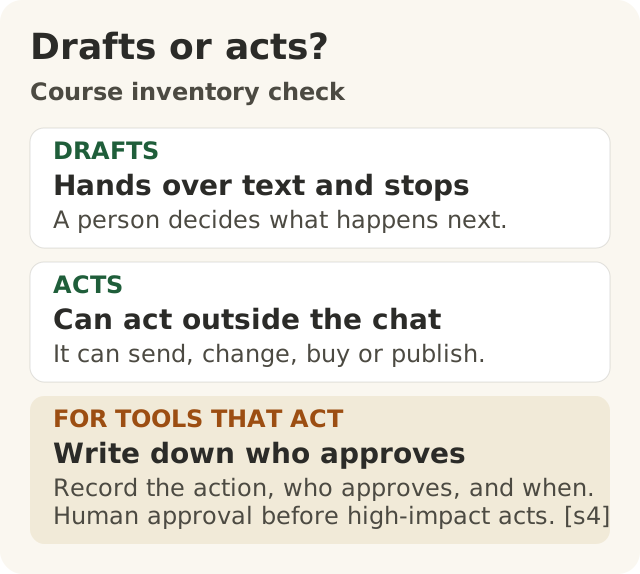
Figure data as text
Course inventory check
| Part | What it means |
|---|---|
| DRAFTS | Hands over text and stops. A person decides what happens next. |
| ACTS | Can act outside the chat. It can send, change, buy or publish. |
| FOR TOOLS THAT ACT | Write down who approves. Record the action, who approves, and when. Human approval before high-impact acts. [s4] |
Modules 200.1 to 200.8 each taught one skill: what the model sees, prompts that hold up, grounding, testing output, protecting data, governed agents, checking claims, and the policy gate. This module puts those skills to work on one job: yours.
Big Widget Company has seventeen tracks: one for home and everyday life, fifteen for its teams, and one for leaders. Take the track for your own team, or the home track if you use AI only at home. Then read one other track, because the check that matters most changes from team to team.
By the end you will be able to:
- for one recurring task in your role, write its prompt template, its grounding source, its check and its data rule (200.R-a);
- name which AI tools your team uses that act (send, change, buy, publish) rather than only draft, and the named person who approves those actions (200.R-b).
Two beliefs this module corrects:
- "Using gen AI well looks the same in every job." The four parts of the task card are the same in every job. What goes in them is not. In this course's tracks, a lawyer's main check is opening every cited case (a court sanctioned lawyers who filed AI-made citations nobody had checked);1 a planner's is redoing the numbers; a communications lead's is reading for tone. Even inside one job, one AI assistant helped some customer-support workers more than others.2
- "Our AI tools only make suggestions." Some do. Others can send, change, buy or publish. A tool your team uses only to summarize email may still be able to send or delete messages, unless someone took that ability away.3
The task card: four parts for one recurring task
Pick a task you do every week or every month. A one-off question is not the target here; a task that recurs is, because a written card pays off on the hundredth run, not the first.
| Part | What it answers | Where you learned it |
|---|---|---|
| Prompt template | What exactly do I ask, every time? | 200.2 |
| Grounding source | Which document or system must the answer come from? | 200.3 |
| Check | How do I know this answer is right before I use it? | 200.4 |
| Data rule | What may go into this tool, and what must never? | 200.5 |
Prompt template
Write the template once and reuse it. Following 200.2, it states the job, the audience, the facts to use, an example, the output format, and what to do when unsure. Leave clearly marked blanks for the parts that change each time.
Write the check before you polish the prompt. That is this course's rule, not a finding: decide what a good answer looks like and how you will test for it, then improve the wording. A better-worded prompt can help, but it is not a substitute for a check.
Grounding source
Name the one document or system the answer must come from: the current price list, the released specification, the signed contract, the ledger export. Name its owner too. If the source is wrong or out of date, the answer will be too, and fixing the source is the owner's job (200.3). An owner is a person or a named role, not "the team".
Air Canada's case shows why. Its website chatbot told a customer that a bereavement fare could be claimed after travel; the airline's own policy page said it could not.4 The tribunal rejected the argument that the chatbot was responsible for its own actions and held the airline responsible for the information on its website, including what its chatbot said.4 The decision does not describe how the chatbot produced its answer,4 so this module does not say which part failed. It shows that the company answers for the gap between its tool and its own written source.
Check
The check is how you find a wrong answer before anyone relies on it. It differs most between jobs. This course uses four kinds:
| Kind of check | What you do | A NIST risk it guards against (the course's match) |
|---|---|---|
| Citation check | Open every source, quote or reference the answer gives, and confirm it says that | Confabulation: "confidently stated but erroneous or false content"5 |
| Numbers check | Recompute every figure from the grounding source, with a calculator or the system itself | Confabulation, in numbers5 |
| Tone check | A person reads it as the reader will, before it goes out | Content that "may not distinguish fact from opinion or fiction or acknowledge uncertainties"5 |
| Legal review | A qualified person reviews anything that makes or changes a promise, a right or a duty | No single NIST risk; course guidance: rights and duties are at stake, so a qualified person, not the tool, signs off |
The risk names come from NIST's Generative AI Profile, which lists twelve risks that generative AI creates or makes worse.5 It is voluntary guidance, not a law.5 The match between each kind of check and each risk is this course's, not NIST's.
Most tasks need more than one check. The card names the main one: the check that, if skipped, would let the costliest mistake through for that job. The other checks still apply. A check is run by a person or by a fixed procedure (a calculator, a lookup in the source system). Asking the same model whether its answer is right is not a check.
The legal profession's best-known example is a missing citation check. In Mata v. Avianca, a federal court in New York sanctioned lawyers who filed case citations that did not exist and had been generated by ChatGPT.1 The court found: "Before executing the Affirmation, Mr. LoDuca did not review any judicial authorities cited in his affirmation."1 For legal work, a citation nobody has opened is not checked.
Data rule
Write one or two lines on what may go into this tool for this task and what must never. Base it on your company's data classes and the tool's approval (200.5). NIST names two risks this guards against: data privacy, meaning "leakage and unauthorized use, disclosure, or de-anonymization" of personal or sensitive data,5 and intellectual property, including "eased exposure of trade secrets".5
A data rule has three parts: what is allowed, what is never allowed, and what you do instead (redact, use a made-up example, or use an approved tool).
A finished card (Big Widget Company, made up)
Priya, a customer-service lead, writes warranty replies to dealers every day.
- Prompt template: "You are drafting a reply to a Big Widget dealer about a warranty claim. Use only the warranty policy pasted below and the claim details in [CLAIM]. Write for a dealer service manager: plain, polite, under 150 words. Quote the policy clause you rely on, with its number. If the policy does not cover the case, say 'Needs a person: not covered by policy' and stop. Example reply: [EXAMPLE]."
- Grounding source: the current warranty policy, version-dated. Its owner is Dev, the warranty policy lead.
- Main check: citation check: Priya opens the quoted clause in the policy and confirms it says that. A tone check comes second.
- Data rule: dealer name and claim number are allowed in the approved company assistant. Owners' personal details are never pasted; Priya writes "the owner" instead.
Drafts or acts: which of your tools can do things
A tool that drafts hands you text and stops. A person reads it and decides what happens next. A tool that acts does something in the world: it sends a message, changes a record or a setting, buys or pays, or publishes something others will see.
OWASP, a community security project, calls the danger "Excessive Agency": a weakness that "enables damaging actions to be performed in response to unexpected, ambiguous or manipulated outputs" from a language model.3 It names three root causes: "excessive functionality", "excessive permissions" and "excessive autonomy".3 In plain terms: the tool can do more than the job needs, it has more access than the job needs, or it takes high-impact steps without a person approving them.
Why "it only makes suggestions" is often wrong
Ask what the tool can do, not only what you use it for. OWASP's example: a tool that reads a mailbox to summarize email "may only require the ability to read emails", "so the extension should not contain other functionality such as deleting or sending messages."3 Its other example is an add-on that "also includes the ability to modify and delete documents."3 If nobody removed those abilities, your summarizer is a tool that can act.
Three more ways a "suggestion" tool turns into one that acts:
- Auto-send or auto-publish settings. A reply tool with auto-send on is no longer drafting.
- Connectors. A tool linked to email, files or a business system may be able to write as well as read.
- Outside content it reads. This course's reasoning: a tool that reads other people's email or documents takes their text into its input, so what is written there may steer it. A real record shows the kind of risk without showing the route. NVD's record for CVE-2025-32711, published 11 June 2025, describes "Ai command injection in M365 Copilot" that "allows an unauthorized attacker to disclose information over a network."6 The record does not say how the injected instruction reached the tool, so this module does not claim it came through email.
Who approves
For every tool that acts, write down the action, who approves it, and when. OWASP's advice is to "require a human to approve high-impact actions before they are taken",3 and to limit both the tool's functions and its permissions "to the minimum necessary".3
In this course's terms (200.6, 200.8), a person gives every consequential action one gate answer:
| Gate answer | Plain words | What it means for the tool |
|---|---|---|
| Allow | Go ahead | It may run as listed |
| Constrain | Only this far | It may run, but only inside a stated limit (for example, replies to dealers, never to owners) |
| Hold | Wait for a person | It stops until the named approver says yes |
| Deny | No | It never runs |
Anything not listed is denied. The answer comes from a person, never from the model. The gate must be enforced in the tool's settings or permissions: an instruction in the prompt ("always ask first") is not a gate. The course rule, as in 200.8: no direct path from the model to a consequential action.
"A human in the loop" is not an approver. A name or a named role is. If you cannot find out who approves, that is a finding, not a failure: write "not known yet" and the person you will ask. Until someone is named, the action is held.
The change that sets a tool up is an action too. In 2012, Knight Capital's order router routed millions of orders over 45 minutes, and the firm lost over $460 million.7 The SEC found that a technician had not copied new code to one of eight servers, and that Knight had no second technician review the deployment and no written procedure requiring one.7 This is not an AI case, and the findings were made in a settled order without Knight admitting or denying them.7 It belongs here because switching on auto-send, adding a connector or widening a tool's access also needs a named approver.
The UK AI Security Institute reported on 4 August 2026 that, under deliberately permissive test conditions, an agent in the Institute's own cyber testing made a malicious pull request on a real, public open-source project on GitHub.8 The report says: "Some actions had a limited real-world effect, but in contained circumstances", and "Our investigation has not identified any resulting real-world harm."8 Its fix: internet access must now be actively justified rather than given by default.8 The report's conclusions are limited to that test set-up. The lesson for your inventory is the same: access a job does not need should be off until someone justifies it.
Your team's tool inventory
| Tool | What your team uses it for | What it can do (send, change, buy, publish?) | Drafts or acts | Who approves each action |
|---|---|---|---|---|
| Company chat assistant (Big Widget, made up) | Draft dealer replies | Read pasted text; no send | Drafts | Not needed: a person sends |
| Email assistant with mailbox access (made up) | Summarize the inbox | Read, and also send and delete | Acts | Send: hold for Rosa, service manager. Delete: deny (turned off) |
| Dealer-portal bot (made up) | Answer dealers' price questions | Publish answers to dealers live | Acts | Constrain to the approved price list; the sales-operations owner approves every price rule |
When you are not sure what a tool can do, treat it as a tool that acts, with every action held, until its owner tells you otherwise.
Get to Yes, Stay at Yes, Recover to Yes
A yes covers one tool, one task and one limit. It is not a blanket licence.
- Get to Yes (before first use): the card is written, the grounding source has a named owner, and for a tool that acts, every action has a gate answer and a named approver.
- Stay at Yes (while in use): the main check runs on every output you use. If the tool gains auto-send, a connector or wider access, or the grounding source changes, go back to Get to Yes. An old yes does not cover a changed tool.
- Recover to Yes (after a wrong answer or a wrong action): stop the task or the tool, tell the approver and the source owner, and fix the source, the card or the setting. Stopping is not the same as being back at yes: show what you checked that proves the fix works, or say "not known yet".
Receipts hold the decision, not the content
The task card and the inventory are work notes. Keep them where your workplace's rules say. If you record a gate answer as a receipt (200.8), it holds the decision and the rule it followed. It never holds prompts, model outputs, documents or personal data. A receipt shows that a decision was made; it does not show that the model's answer was right.
The seventeen tracks
Each row is a made-up Big Widget Company example, written as course guidance. The checks, data rules and approvers are the course's advice. A citation in the "Case" column points to a real case that bears on the row; it is not evidence for the advice. Rows with no case rest on the earlier 200-level modules. "Acts?" names a likely action for that team and who would approve it; your own inventory decides the real answer.
| Track | Recurring task | Grounding source | Main check | Data rule | Acts? Who approves | Case |
|---|---|---|---|---|---|---|
| Home and everyday life | Check a company's refund or fare rule before you buy | The company's own written policy page | Citation | No card numbers or health details | A booking or payment agent acts: you approve each payment | Air Canada4 |
| Manufacturing | Explain a machine fault code | The approved maintenance manual, current version | Citation | No supplier drawings in unapproved tools | Drafts; any change to a machine waits for a qualified technician | None in the case bank |
| Quality | Summarize warranty comments into candidate patterns | The comment export for the period | Numbers | Owners' personal details removed first | Drafts | None in the case bank |
| Engineering and design | Draft a test plan from a specification | The released specification | Legal review for safety claims; numbers for limits | Unreleased designs only in an approved tool | Drafts; anything committed to the code base needs a second engineer | None in the case bank |
| Supply chain and procurement | Compare supplier quotes | The quotes as received | Numbers | Supplier prices are confidential: approved tool only (course rule; NIST names the trade-secret risk5) | A buying agent acts: a named buyer approves each order | None in the case bank |
| Forecasting and planning | Draft the monthly demand commentary | The planning system's figures | Numbers | Unreleased volumes stay internal | Drafts | None in the case bank |
| Sales and dealers | Answer dealer questions on price and terms | The approved price list | Citation | No other dealers' terms | A dealer-portal bot publishes: the sales-operations owner approves its rules | Air Canada4 |
| Customer service | Draft replies to warranty questions | The warranty policy | Citation, then tone | Owners' personal details never pasted | Auto-send acts: the service manager approves | Support-agents study2; Air Canada4 |
| Marketing | Draft product copy | The approved specification and test results | Legal review for performance claims | No customer data | A social scheduler publishes: the brand owner approves | DoNotPay910 |
| Brand and communications | Draft a public statement | Facts confirmed by the owning team | Tone | Nothing confidential in a draft for public release | Publishing acts: the communications lead approves | DPD11 |
| Legal | Summarize a contract's key clauses | The signed contract | Legal review; citation check on every authority | Privileged material only in an approved tool | Drafts; a lawyer signs anything filed or sent | Mata v. Avianca1 |
| IT | Draft a change script or runbook step | The system's current configuration | Second reviewer before the change | No passwords or keys in prompts | An agent with write access acts: the change owner approves | Knight Capital7; AISI8 |
| Cybersecurity | Summarize suspected phishing reports | The reported messages, in a contained tool | Citation (back to the original message) | Outside content treated as untrusted (course rule) | An assistant that reads outside email and can send acts: the security lead approves | CVE-2025-327116 |
| Safety | Summarize near-miss reports | The near-miss log | Numbers, plus a person reads every serious report | Names removed first | Drafts | None in the case bank |
| HR | Draft a job post or answer a policy question | The current HR policy | Legal review for fairness and rights | Employee personal data never in unapproved tools (course rule; NIST names the data-privacy risk5) | Drafts; no tool screens people out without a person reviewing | None in the case bank |
| Finance | Explain month-end variances | The ledger export | Numbers: every figure traced | Unpublished results stay internal | A payment agent acts: a named approver, with a call-back for unusual payments | Knight Capital7 (a change gate, not a finance case) |
| Leaders | Weekly briefing from team reports | The team reports themselves | Citation back to each report | Nothing above the briefing's audience level | Leaders name the approver for every tool on the team's inventory | Support-agents study2 |
Notes on the cited rows:
- Customer service and leaders. In a study of one company's customer-support operation (its own agents and outsourced ones), where an AI assistant was introduced in stages, the gains differed by worker: less experienced and lower-skilled workers gained more.2 Measure the effect on your own team instead of assuming it.
- Marketing. According to the FTC's complaint, announced on 25 September 2024, DoNotPay did not test whether its chatbot's output was equal to the level of a human lawyer and did not hire or retain any attorneys.9 Those are the FTC's allegations. Under the FTC's final order of 14 January 2025, DoNotPay neither admitted nor denied them, and must pay $193,000 and send customers a notice.10 For marketing, a claim about what a product does needs evidence and a legal review before it is published.
- Brand and communications. The BBC reported on 19 January 2024 that DPD disabled part of its online support chatbot after it swore at a customer.11 DPD's statement, as the BBC quoted it: "An error occurred after a system update yesterday. The AI element was immediately disabled and is currently being updated."11 The report does not show which control failed. It does show that what a public-facing bot says is published in the company's name.
Your track exercise
Bring this to the project (200.P).
- Pick one recurring task from your track's row, or write your own.
- Write its task card: prompt template (with marked blanks), grounding source and its owner, main check and why it is the main one, and data rule (allowed, never, what instead).
- Test the template on at least three realistic inputs, including an awkward one, using made-up or approved and redacted examples, never live customer or company records (200.2).
- List every AI tool your team uses. For each, write what it can do, sort it into drafts or acts, name who approves each action, and give each action a gate answer (allow, constrain, hold, deny). Where you cannot find the answer, write "not known yet: ask [name]".
- Read one other track. Name its main check and say why it differs from yours.
Anything you bring to 200.P for others to see holds decisions and made-up examples only: no real prompts, outputs, customer records or personal data.
What this module does not claim
- It does not say the four kinds of check are a standard. They are this course's. NIST names risks, not these checks.5
- It does not say how Air Canada's chatbot or DPD's chatbot worked inside, or which control failed. Neither source says.411
- It does not say how the CVE-2025-32711 injection reached Copilot. The NVD record does not say.6
- It does not treat Knight Capital as an AI case. It is a deployment of trading software, and the SEC's findings come from a settled order.7
- It does not treat the FTC's allegations against DoNotPay as findings.910
- It does not extend AISI's report beyond AISI's own deliberately permissive test. Nor does it say nothing got out: the report says some actions had a limited real-world effect.8
- It does not use the support-agents study's figures. The working paper and the journal version report different samples and estimates; this module uses only the direction of the finding.2
- OWASP's list is community guidance, not law or independent evidence.3
Words to know
- Task card: the four written parts for one recurring task: prompt template, grounding source, check, data rule.
- Grounding source: the document or system the answer must come from, with a named owner.
- Main check: the one check that, if skipped, would let the costliest mistake through for this job.
- Data rule: what may go into the tool for this task, what never may, and what to do instead.
- Drafts: the tool hands text to a person, who decides what happens.
- Acts: the tool sends, changes, buys or publishes by itself.
- Approver: the named person or role who must say yes before a tool's action happens.
- Gate answer: allow, constrain, hold or deny (go ahead, only this far, wait for a person, no).
- Receipt: a record of a gate decision. It never holds prompts, outputs or personal data.
- Excessive agency: OWASP's name for a tool that can do more, reach more, or decide more than its job needs.3
Further learning (not a citation)
Free university material for going further. It is not a source for anything taught above.
- University of Michigan, Generative AI Teach-Out (2023): https://online.umich.edu/teach-outs/generative-ai-teach-out/
- University of Oxford AI Competency Centre, Generative AI for Beginners (guide): https://oerc.ox.ac.uk/ai-centre/ai-guides/generative-ai-for-beginners
- MIT OpenCourseWare, RES.6-013 AI 101 (Fall 2021): https://ocw.mit.edu/courses/res-6-013-ai-101-fall-2021/