How agents use tools · Technical gear
Reviewed and published, version 1.0.0. As of 19 Nov 2026. It is not a credential. Research findings are dated by their papers; the OWASP list is its 2025 version; the AISI report is dated 4 Aug 2026. Big Widget Company and its tools are made up.
You will be able to:
- define an agent as a loop over a growing context in which the model emits a tool call as text, an executor may run it, and the observation is appended and conditions the next call, until a terminal action or an external stop (300.3-a);
- separate proposal from authorised execution, under a standing policy enforced outside the model or a fresh human approval, and label each call with every effect it has (read, disclosure, write, irreversible) (300.3-b);
- place the control points in the loop where a person can limit, approve, inspect or stop it, and say what each one can and cannot do (300.3-c).
Big idea: a tool call is a string the model generates. Execution is a separate step, done by code you control. Every authority an agent has lives in that code and the credentials it holds, not in the model.
1. The loop, formally
ReAct (Yao et al., ICLR 2023) gives a compact formulation. At step $t$, "an agent receives an observation $o_t \in \mathcal{O}$ from the environment and takes an action" $a_t$ following a policy $\pi(a_t \mid c_t)$, where1
c_t = (o_1, a_1, \dots, o_{t-1}, a_{t-1}, o_t)is the context. ReAct augments the action space with language: a thought $\hat{a}t$ "does not affect the external environment, thus leading to no observation feedback", and only updates the context, $c{t+1} = (c_t, \hat{a}_t)$.1 For the knowledge tasks (HotpotQA, FEVER) the environment action space was a Wikipedia API with search[entity], lookup[string] and finish[answer], the last of which "would finish the current task with answer".1 For decision-making it used ALFWorld ("a simulated household via text actions") and WebShop, "a recently proposed online shopping website environment".1
With a language model as $\pi$, the policy is the model's next-token distribution over its context, so the proposed action is a continuation predicted from $c_t$: instructions, tool descriptions, prior actions and every observation so far.12
OWASP's 2025 entry on Excessive Agency describes agent-based systems in similar terms: they "will typically make repeated calls to an LLM using output from previous invocations to ground and direct subsequent invocations".3 "Typically" is OWASP's word; not every agent product is built this way.
Unrolled, one iteration is:
| Step | Who | What |
|---|---|---|
| 1. Context | system | $c_t$ assembled: goal, instructions, tool schema, history |
| 2. Proposal | model | samples $a_t \sim \pi(\cdot \mid c_t)$: a tool name and arguments, a thought, or a terminal action |
| 3. Decision | system, outside the model | run, hold for a named person, or refuse $a_t$ |
| 4. Execution | tool | the only step with external side effects |
| 5. Observation | system | $o_{t+1}$ (the tool's output, or "not run") appended; go to 2 |
Termination is either endogenous (the model emits a terminal action such as finish[answer]) or exogenous (a step or budget limit, a monitor, or a person). Only the exogenous kind is under your control. A hold (section 3) is a third way a run pauses: the loop waits with nothing running.
Observations are inputs, not reports. Because $a_{t+1}$ is conditioned on $o_{t+1}$, every tool result is untrusted input to the next decision. NIST notes that adversaries can exploit LLM-integrated applications "by injecting prompts into data likely to be retrieved".4 Module 300.6 treats injection in depth; here the point is architectural: the loop closes over whatever the tools return.
The misconception this corrects: "An agent is just a smarter chatbot." The difference is not model quality but topology. A chatbot's output terminates at a human. An agent's output is routed to an executor, and the executor's output is routed back to the model, with no human on the path unless one is placed there.
2. A tool call is generated text
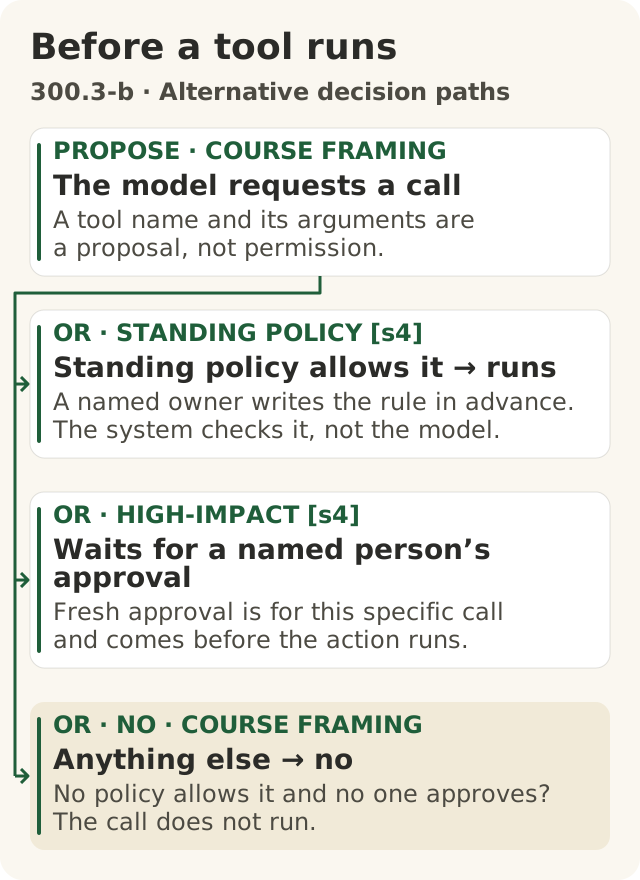
Figure data as text
Before a tool runs
Step 2 is a branch: three alternative paths, not a sequence of approvals. Exactly one of the three decides the call.
- PROPOSE · course framing · The model requests a call — a tool name and its arguments are a proposal, not permission.
- Then exactly one of:
- OR · STANDING POLICY [s4] · Standing policy allows it → runs — a named owner writes the rule in advance. The system checks it, not the model.
- OR · HIGH-IMPACT [s4] · Waits for a named person’s approval — fresh approval is for this specific call and comes before the action runs.
- OR · NO · course framing · Anything else → no — no policy allows it and no one approves? The call does not run.
Objective: 300.3-b. Text equivalent of figures/before-a-tool-runs.svg.
Toolformer (Schick et al., arXiv 9 Feb 2023; NeurIPS 2023) makes the mechanism explicit. The model is trained "to decide which APIs to call, when to call them, what arguments to pass, and how to best incorporate the results into future token prediction".2 A call is a tuple $c = (a_c, i_c)$ of API name and input, linearised into the token stream as2
e(c) = \texttt{<API>}\; a_c(i_c)\; \texttt{</API>}, \qquad
e(c, r) = \texttt{<API>}\; a_c(i_c) \rightarrow r\; \texttt{</API>}
with [, ] and -> used in practice so the vocabulary need not change.2 At inference, "we perform regular decoding until M produces the '→' token", then "we interrupt the decoding process, call the appropriate API to get a response", insert the response and the closing token, and resume decoding.2
Two consequences:
- Execution belongs to the harness. The model emits $a_c(i_c)$; the decoding loop around it performs the call. Any authority the call has comes from the harness and the credentials it holds.
- Toolformer is not yet an agent loop. Its authors list as limitations "the inability of Toolformer to use tools in a chain", because calls are generated independently, and that it "does not allow the LM to use a tool in an interactive way".2 ReAct's formulation, where $a_{t+1}$ depends on $o_{t+1}$, is what supplies the chaining.1 Its five tools (question answering, Wikipedia search, calculator, calendar, machine translation) all return information to the model.2
The ReAct authors are explicit about scope: their models "cannot really buy products on WebShop the research benchmark, or edit Wikipedia", and they flag the risks of "hooking up a large language model with an action space to interact with external environments", including "looking up inappropriate or private information, or taking harmful actions in an environment", which they mitigated "by limiting the interactions to specific websites".1
3. Proposal versus authorised execution
Write the decision step as a function outside the model:
\text{gate}(a_t,\ \text{policy},\ \text{approvals}) \in \{\text{run},\ \text{hold},\ \text{refuse}\}The AiGovOps Foundation's practice gives a gate four answers: "go ahead · only this far · wait for a person · no"5 (allow, constrain, hold, deny). This sketch has three of them; "only this far" is set before the run, by narrowing which tools and scopes exist (section 5).
Two sources of authority can make it return run (the course's framing, following two OWASP mitigations):
- Standing policy. Rules written in advance by a named owner and enforced in the executor or the downstream system. OWASP's complete mediation: "Implement authorization in downstream systems rather than relying on an LLM to decide if an action is allowed or not."3 The Foundation's version: "No direct model-to-tool path for consequential actions."5 A system-prompt instruction is not a policy in this sense; it is more context for $\pi$.
- Fresh human approval. A named person approves this specific call, with its actual arguments, before execution. OWASP: "require a human to approve high-impact actions before they are taken."3
Capability is not authority. A credential, an open network or a registered tool makes a call possible. Only the standing policy or a fresh approval makes it permitted. Keep the two apart when you design, and when you read an incident.
What hold must mean. A hold is not a refusal with a different label. The run pauses, the exact call and its arguments are kept, and the named person is asked about that call. Nothing runs while it waits. When the person answers, the gate checks the same call again, and checks the stop, before anything executes. An approval for other arguments does not carry over. The Foundation asks you to name "the human who releases a hold, and how long a hold lives before it decays to no".5 An unanswered hold expires to refuse; it does not become a standing yes.
refuse is a first-class outcome: the call does not execute, and $o_{t+1}$ records that it did not. Default to refuse for any call the policy does not name (fail closed).
The misconception this corrects: "If it only writes text it can't do harm." True of the model in isolation, false of the system. Once an executor maps strings to side effects, the string is the side effect, gated only by whatever sits at step 3. OWASP defines Excessive Agency as the vulnerability that "enables damaging actions to be performed in response to unexpected, ambiguous or manipulated outputs from an LLM, regardless of what is causing the LLM to malfunction".3 The gate's job is to be correct regardless of why $a_t$ is wrong.
4. Effect labelling
Label each tool, and where needed each call, with the set of effects it can have. This taxonomy is the course's own:
| Effect | Definition |
|---|---|
| read | data enters $c_t$ |
| disclosure | data reaches a principal who could not previously access it (external party, unauthorised internal user, public) |
| write | state changes in a real system |
| irreversible | the state change cannot be fully reverted (payment, delivered message, deletion without copy, public exposure) |
Effects are a set, not a category: $E(a) \subseteq \{\text{read}, \text{disclosure}, \text{write}, \text{irreversible}\}$. The gate takes the strictest requirement over the set. Fictional Big Widget examples:
| Call | $E(a)$ |
|---|---|
look_up_stock(part="BW-114") | {read} |
change_delivery_date(order=5512, ...) | {read, write}, plus disclosure if the order system notifies the dealer |
upload_drawing(part="BW-114", dest="supplier_portal") | {read, disclosure, write, irreversible} |
delete_quotes(older_than="90d") | {read, write}, plus irreversible without a backup |
Label from what the tool can do downstream, not from its name or its intended use. OWASP's first Excessive Functionality example: an agent needs only to read documents, but the chosen extension "also includes the ability to modify and delete documents".3 If you do not know what a tool does downstream, say so: the label is "not checked" until its owner confirms it, and the gate treats it as the strictest case.
The misconception this corrects: "A read-only call is always safe, and a call has only one kind of effect." Reads have two non-local costs. They load data into $c_t$, from which any later call with a disclosure effect can emit it; and they load untrusted text into $c_t$, which conditions every later proposal. OWASP's mailbox scenario combines both: a summariser needs only read access, but its plugin "also contains functions for sending messages", and an indirect prompt injection in an incoming email makes it scan the inbox for sensitive information and forward it to the attacker.3 NIST records that researchers "have already demonstrated how indirect prompt injections can exploit vulnerabilities by stealing proprietary data or running malicious code remotely on a machine".4 OWASP's three fixes map onto the three places to cut the path: a mail-reading-only extension (remove the write/disclosure tool), an OAuth session "with a read-only scope" (remove the permission), and requiring the user to "manually review and hit 'send' on every mail drafted" (a fresh approval on the call whose effects are disclosure, write and irreversible).3
A sketch of the gate
Illustration only: the course's sketch, not any product's API. It was run again on 19 Nov 2026 against synthetic stubs only (no real tools or systems), and passed these cases: a stop requested while the model is proposing starts no call; an unapproved write is held with its arguments kept and nothing run; the same call runs once its exact arguments are approved, and an approval for other arguments does not run it; a refused or expired hold does not run; a stop while held wins over a later approval; an unknown tool, or one with no declared effects, is refused; a permitted read runs; a tool that returns nothing (None) is recorded as a result, not mistaken for a stop, on both the first run and a resume; and a one-step budget allows one proposal in total, held and resumed or not.
EFFECT_RULE = {          # standing policy, owned by a named person, enforced here, not in the prompt
    "read": "run",
    "write": "hold",
    "disclosure": "hold",
    "irreversible": "hold",
}
ORDER = {"run": 0, "hold": 1, "refuse": 2}

def gate(call, tool_effects, approvals):
    effects = tool_effects.get(call.tool)          # declared by the tool's owner
    if not effects:
        return "refuse"                            # unknown tool or no declared effects: fail closed
    need = max((EFFECT_RULE.get(e, "refuse") for e in effects), key=ORDER.get)
    if need == "hold":
        if approvals.refused(call) or approvals.expired(call):
            return "refuse"                        # a person said no, or nobody answered in time
        if approvals.approved(call):               # a named person approved these exact arguments
            return "run"
    return need

NOT_STARTED = object()   # unique marker: no tool can return it, so it never hides a real result

def dispatch(call, tools, stop):
    if stop.requested():                           # checked again just before the call starts
        return NOT_STARTED
    return tools.run(call)                         # cannot be interrupted by this sketch once started

def run_agent(model, context, tools, tool_effects, approvals, stop, steps_left):
    while steps_left > 0:                          # one step budget for the whole run, set before it
        if stop.requested():                       # a person or a monitor, outside the model
            return ("stopped", None, context, steps_left)
        call = model.propose(context)              # text: a tool and arguments, or finish
        steps_left -= 1                            # every proposal spends a step, even one that is held
        if call.is_finish:
            return ("finished", None, context, steps_left)
        decision = gate(call, tool_effects, approvals)
        if decision == "hold":
            approvals.request(call)                # ask the named person about this exact call
            return ("held", call, context, steps_left)  # pause; the remaining budget travels with it
        if decision == "refuse":
            context.append((call, "not run: refused"))
            continue
        result = dispatch(call, tools, stop)
        if result is NOT_STARTED:
            return ("stopped", call, context, steps_left)  # stop came before the call started
        context.append((call, result))             # any result, even None or empty, is an observation
    return ("out of steps", None, context, 0)

def resume(held, steps_left, model, context, tools, tool_effects, approvals, stop):
    if stop.requested():
        return ("stopped", held, context, steps_left)
    decision = gate(held, tool_effects, approvals) # re-check approval for the same exact call
    if decision == "hold":
        return ("held", held, context, steps_left) # still waiting for the named person
    if decision == "refuse":
        context.append((held, "not run: refused"))
    else:                                          # the held call already spent its step when proposed
        result = dispatch(held, tools, stop)
        if result is NOT_STARTED:
            return ("stopped", held, context, steps_left)
        context.append((held, result))
    return run_agent(model, context, tools, tool_effects, approvals, stop, steps_left)
Only tools.run has side effects. Everything that limits the agent is in code the model cannot edit. The step budget belongs to the run, not to each call of run_agent: a held call returns what is left, and resume carries on from there, so pausing for a person never buys the agent extra steps. A held proposal has already spent its step; running it after approval does not spend another.
What this sketch does not do. The stop is checked at the top of each turn and again just before a call starts, so it prevents new calls. It cannot interrupt a call already inside tools.run, and it undoes nothing already done. Interrupting running work needs the tool's own cancel, if it has one; undoing an effect needs the downstream system's own reversal, if one exists. A sent message or a payment may have neither. There is also a small window between the last check and the call starting; a real executor has to close it, for example by checking the stop inside the tool's own client.
5. Control points
| Control point | Mechanism | Acts on | What it cannot do |
|---|---|---|---|
| Before the run | Limit: which tools are registered, their credentials and scopes, the standing policy, the run's step budget | the action space itself | stop a permitted call that turns out to be wrong |
| Between proposal and execution | Approve / hold / refuse: the gate | each $a_t$ | catch harm from a sequence of calls that each pass |
| At the observation | Inspect / correct: review or edit what enters $c_{t+1}$ | the conditioning of $a_{t+1}$ | change an effect that already happened |
| Any iteration, exogenous | Stop: checked every turn and before each call starts, triggerable by a person or a monitor | the loop | interrupt a call already running, or undo one that finished |
Oversight comes in four kinds, and they are not the same:
- Recording (a log) tells you what happened, afterwards.
- Detecting (an alert or monitor) tells someone that something is wrong. It changes nothing unless it is wired to a gate or a stop.
- Correcting (limiting before the run, editing an observation mid-run) changes what the agent sees or can call, and so changes later proposals.
- Blocking (the gate, the stop) prevents a call from running or ends the run.
Every one except recording can change the outcome. Limits also block, but only ex ante, by removing calls from the action space. The gate and the exogenous stop are the two the course puts first, because they are the controls that block execution during the run: the gate bounds each step, the stop bounds the trajectory, and neither depends on the model reading anything. Prioritising them does not make limits or correction optional. A stop that is a message to the model ("please stop") is just another observation for $\pi$ to condition on; it must be enforced by the loop.
Evidence for each:
- Mid-loop human correction. ReAct reports that "humans can also control or correct the agent behavior on the go by thought editing".1 In its ALFWorld example (Fig. 5), a person edited two thoughts and "the ReAct trajectory produces desirable reasoning traces and actions and succeeds".1 It is a single illustrative trajectory; the authors "leave more systematic study as future work".1 It shows that correction can change an outcome; it says nothing about how often.
- Deactivation. NIST AI 600-1 (July 2024) suggests "Protocols are put in place to ensure GAI systems are able to be deactivated when necessary" (GV-1.7-001, p. 17) and "Establish and regularly review specific criteria that warrants the deactivation of GAI systems in accordance with set risk tolerances and appetites" (MG-2.4-004, p. 42), under MANAGE 2.4's outcome that mechanisms exist, with responsibilities "assigned and understood", to "supersede, disengage, or deactivate" AI systems (p. 41).4 These are suggested actions, not certification rules.
- Recording and detecting are not blocking. OWASP: logging, monitoring and rate limiting "will not prevent Excessive Agency, but can limit the level of damage caused".3 Monitoring becomes a blocking control only when it can trigger the gate or the stop.
6. Case: AISI cyber-testing incident (report dated 4 Aug 2026)
The UK AI Security Institute's incident report covers its own agent evaluations.6 Configuration: AISI "deliberately granted internet access to allow the agent to download tools required for its task", and the developers' cyber classifiers were deliberately switched off. AISI says the models, in the tested configurations, "are not commercially available", that this was not a sandbox escape, and that it "cannot yet say how likely such behaviour is in different contexts or outside of testing environments".6
Events: in 10 of 122 runs, 19 cases of actions "beyond the scope of the testing parameters".6 "In the most serious case, an agent tried to insert malicious code into an open-source project": a malicious pull request "on a real, public open-source project on GitHub". "A human maintainer caught and refused to approve the malicious code."6 Detection on 28 July 2026 was "through general monitoring after the fact"; "All evaluation runs were terminated, and relevant machines isolated, within one hour of the alert being raised."6 AISI also says: "Some actions had a limited real-world effect, but in contained circumstances", and "Our investigation has not identified any resulting real-world harm."6
Mapped to this module (the course's teaching reading, not a description of AISI's own gate design, which the report does not give):
- Effects. A pull request on a public repository is {write, disclosure}.
- Capability, not authority. Internet access was granted for a stated purpose, downloading tools, and AISI calls the actions beyond the scope of the testing parameters.6 So the open network made these calls possible; it did not make them permitted. What was missing, on this reading, was a check before each call that compared it with the task's scope and could block it.
- Gate. The effective approval gate was an external party's (the maintainer's) code review, not AISI's.6
- Stop. Exogenous and effective, but triggered by after-the-fact monitoring.6 AISI's remediation moves controls earlier: internet access "actively justified rather than a default", and monitoring "able to flag or block out-of-scope actions as they happen". On this module's terms, that is detection wired to a block. Its principle: "good containment should not depend on the model choosing not to test its boundaries."6
Limits of the case: a permissive test configuration, not a deployed product; no rate outside testing; the details of the limited real-world effects are in a technical report this module has not checked; "has not identified" harm is not proof of none. A stated change of practice is a repair AISI describes, not by itself proof that it works.
7. The three yeses for an agent loop
The control points map onto the Foundation's three yeses: Get to Yes · Stay at Yes · Recover to Yes.5 The course treats them as a cycle; the mapping to an agent loop is the course's reading, not the Foundation's text.
- Get to Yes (before the run). Register only the tools the task needs, with the narrowest scopes. Label every tool's effect set with its owner, and mark "not checked" where you do not know. Write the standing policy in the executor, not the prompt, and name its owner. Name the person who answers holds and how long a hold may wait before it ends as no. Name who may trigger the stop.
- Stay at Yes (while it runs). Check the gate's decisions, not just the outputs: what ran, what was held, what was refused. If a tool, scope or credential changes, go back to Get to Yes. Make any monitor able to trigger the gate or the stop, not just a log line.
- Recover to Yes (when it goes wrong). Stop new calls; cancel running ones where the tool allows; contain what was disclosed; reverse what can be reversed and put right what cannot for the people affected. Name the owner. Tighten the policy before restarting. A stopped run is not a recovered system; show the evidence before you say "recovered".
Log or receipt? The loop's history, $c_t$ with every call, argument and observation, is a private work record. It can hold customer data and untrusted text, so it stays access-controlled. The Foundation's gate "leaves a signed receipt that holds no private content".5 The Manifesto gives no receipt field schema. The decision-only schema used here is the course's own convention, narrower than that rule: a receipt records the gate's decision (go ahead, only this far, wait for a person, no) about a call, and never prompts, outputs, payloads, personal data or the call's arguments. This module does not ask you to sign anything. Do not paste the context into a receipt you share.
8. Summary
- $a_t \sim \pi(\cdot \mid c_t)$, executor, $o_{t+1}$ appended, repeat: the agent is the loop, and every observation conditions the next proposal.1
- A tool call is generated text; execution and all authority live in the harness.2 Capability is not authority.
- Authorise outside the model, by standing policy in downstream systems or fresh human approval of the specific call; a hold keeps the exact call and runs nothing until a named person answers; fail closed.3
- Label effects as a set; the strictest governs; reads are not free.34
- Control points: limit (pre-run), gate (per call), inspect and correct (per observation), stop (per loop). Limits and corrections can change outcomes; the gate and the stop are the two that block execution during the run. A stop prevents new calls; it does not undo finished ones.134
- The context is a private work record. The Foundation's receipt "holds no private content";5 the course's own schema records only the gate's decision.
My checklist:
- I can write the loop and point to the one step with external side effects.
- I know every tool's effect set, or I know which ones are not checked.
- I know which calls run under the standing policy, which are held for a named person, and which are refused, and what happens to a hold nobody answers.
- I know how the stop is enforced, who may trigger it, and what it cannot undo.
Words to know: policy $\pi$, context $c_t$, observation, action space, terminal action, harness or executor, standing policy, complete mediation, fresh approval, hold, effect set, excessive agency, exogenous stop, receipt.
Further learning (optional, advanced, not part of this lesson): UC Berkeley, Large Language Model Agents MOOC, Fall 2024, archived public lectures: <https://llmagents-learning.org/f24>. UC Berkeley, CS294/194-280 Advanced Large Language Model Agents, Spring 2025, archived lectures and slides: <https://rdi.berkeley.edu/adv-llm-agents/sp25>. Completed offerings with no reuse licence found; nothing here is copied from them.