Building in your job (role tracks and prep rails) · Technical gear
Reviewed and published, version 1.0.0. As of 18 November 2026. It is not a credential. Big Widget Company is fictional. Every real organization, record and figure below is cited to a primary source; the two lawsuits' outcomes are not checked. The track structure, the operate gate, its notation and the prep-rail rules are this course's own design, not a standard.
Scope
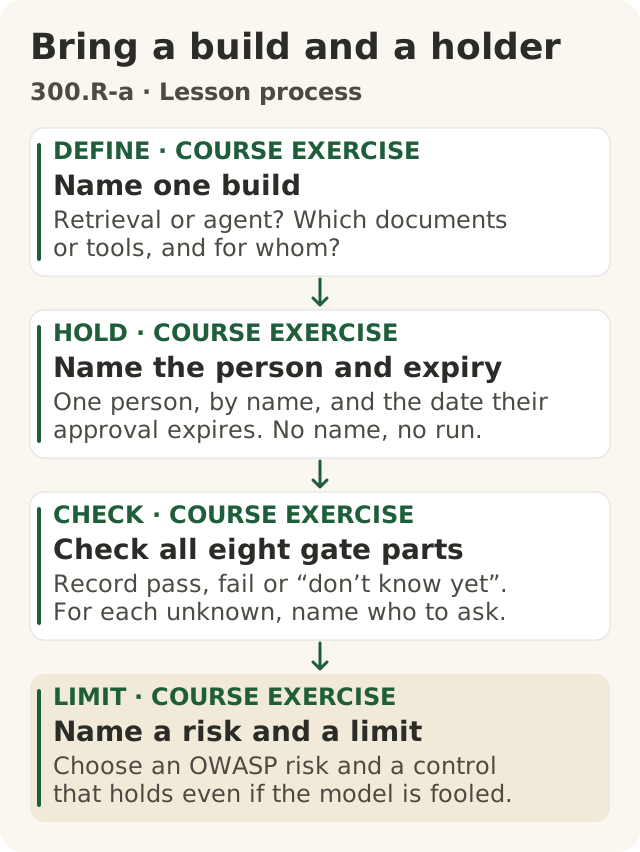
Figure data as text
Bring a build and a holder
- DEFINE · course exercise · Name one build — retrieval or agent? Which documents or tools, and for whom?
- HOLD · course exercise · Name the person and expiry — one person, by name, and the date their approval expires. No name, no run.
- CHECK · course exercise · Check all eight gate parts — record pass, fail or “don’t know yet”. For each unknown, name who to ask.
- LIMIT · course exercise · Name a risk and a limit — choose an OWASP risk and a control that holds even if the model is fooled.
Course track exercise using the OWASP risk list (s3).
Objective: 300.R-a. Text equivalent of figures/bring-a-build-and-a-holder.svg.
This gear treats a role track as a specification problem: for one role, choose a build $b$ (a retrieval pipeline or a tool-using agent), bind it to a single accountable holder, and state the predicate it must satisfy before it runs unattended (300.R-a). It then defines a prep rail as a mapping from course objectives to an external exam's topic list, and states what that mapping does not confer (300.R-b).
| Objective | Formal object | Primary evidence used |
|---|---|---|
| 300.R-a | A build $b = (k, C, T, E)$, its holder $h(b)$ with expiry, and the gate predicate $G(b)$ | NIST AI 100-1, Govern 2.1, 2.3, 3.21; OWASP Top 10 for LLM Applications 2025234; EU AI Act, Commission page5; case records678 |
| 300.R-b | A rail $r: O \to X$ from course objectives to exam topics, and its non-implications | Foundation university-courses page9; course rules (agents/cert-prep.md) |
Two misconceptions are targeted: that building with AI is a developer's job only (300.R-a), and that completing a prep rail confers the vendor certification (300.R-b).
Lifecycle. In the three yeses of module 100.9, writing $b$, $h(b)$ and the authority table and showing every part of $G$ evaluates to $1$ is Get to Yes; re-evaluating $G(a)$ before every action $a$, with coverage reported, is Stay at Yes; a fired stop, the holder's decision, a tested repair and the receipts that evidence it are Recover to Yes. A fired stop alone is not recovery, and an announced repair is not evidence that it worked. The gate's four outcomes per action are allow, constrain, hold and deny (go ahead, only this far, wait for a person, no). The gate decides and $h(b)$ holds; the model decides, signs and marks nothing.
1. The build and its effect set
Define a build as
b = (k,\; C,\; T,\; E), \qquad k \in \{\text{retrieval}, \text{agent}\}where $C$ is the set of collections it may retrieve from (with each document's own access list checked at query time, 300.2-a), $T$ the set of tools it may propose, and $E \subseteq \{\text{read}, \text{disclose}, \text{write}, \text{irreversible}\}$ the union of the effects of its tools (one call can have several, 300.3-b). A pure retrieval build has $T = \varnothing$ but still has $\text{read} \in E$ and, if answers leave the permission boundary of $C$, $\text{disclose} \in E$.
The effect set, not the model, sets the build's blast radius. OWASP's 2025 list for LLM applications names prompt injection (LLM01), sensitive information disclosure (LLM02), excessive agency (LLM06) and vector and embedding weaknesses (LLM08) among its ten risks.2 OWASP traces excessive agency to excessive functionality, excessive permissions or excessive autonomy, and recommends limiting the extensions an agent may call and their permissions "to the minimum necessary", and requiring a human to approve high-impact actions before they are taken.3 In the notation above, those mitigations shrink $T$, shrink $E$, and move actions with $\text{write}$ or $\text{irreversible}$ in their effects from "alone" to "approver".
Because OWASP states that "it is unclear if there are fool-proof methods of prevention for prompt injection", and that indirect injection arrives through inputs from external sources such as websites or files,4 the design assumption is that the model may be steered by anything in $C$ or in a tool result. The control is therefore on $E$, enforced outside the model, not on the prompt: a system prompt is not a permission boundary, and there is no direct model-to-tool path for a consequential action.
2. The holder
The holder is a function to a single person with an expiry:
h(b) = (p, t_{\text{exp}}), \qquad p \in \text{People}, \quad |p| = 1and the build is held at time $t$ only if $p$ is still in role and $t < t_{\text{exp}}$. A team, a distribution list or a role without a named occupant is not in $\text{People}$.
This is stricter than, but consistent with, NIST AI 100-1. Govern 2.1 asks that "roles and responsibilities and lines of communication related to mapping, measuring, and managing AI risks are documented and are clear to individuals and teams throughout the organization"; Govern 2.3 that executive leadership takes responsibility for decisions about risks of AI development and deployment; and Govern 3.2 that policies and procedures define and differentiate roles and responsibilities for human-AI configurations and oversight of AI systems.1 The framework is voluntary.10 It names individuals and teams and does not require a single name. The single-name rule with an expiry is this course's choice of how to meet it, and Govern 2.1's "throughout the organization" is the reason the holder sits in the business role, not only in IT.
Keep decision rights apart from routing. $h(b)$ fixes who holds the authority to stop or resume $b$; it says nothing about who receives the alert. Paging a team's on-call rota is compatible with the rule, provided the build also records an escalation path from the on-call responder to $p$. The course requires that path to be written down, not that $p$ answer every page in person.
3. The gate predicate
The operate gate (levels/300/practice/hold-prompts.md, course-owned, synthetic) is evaluated per action $a$ the build may take. Write it as a conjunction of eight parts:
G(a) = H \land A \land O \land B \land J \land S \land R \land KLet $m(a) \in \{\text{alone}, \text{approver}, \text{never}, \text{unlisted}\}$ be the mode the build's authority table gives $a$.
| Part | Holds ($=1$) when |
|---|---|
| $H$ holder | $h(b)$ is defined and unexpired |
| $A$ authority | $m(a) = \text{alone}$ and $a$ is within its listed constraints, or $m(a) = \text{approver}$ and the named approver's decision for this action $a$ is recorded. $A = 0$ if $m(a) \in \{\text{never}, \text{unlisted}\}$ or $a$ breaks its constraints; $A = \bot$ only while an approver action awaits its decision |
| $O$ out-of-band | if $a$ is irreversible and high-value, confirmation arrives on a channel the requester does not control |
| $B$ budget | per-reviewer and system-wide counts per hour are under their limits, measured on peaks, not averages |
| $J$ judgment | where a qualified person's judgment is the decision, the model's output is an input to it |
| $S$ stop | a missing holder, approval or record yields deny (fail closed) |
| $R$ receipt | a receipt holding no private content (what, holder, approval reference, result, undo) is written; it holds references, never prompts, outputs, payloads or personal data |
| $K$ coverage | over the last closed window $W$, every executed action is matched: its effective gate decision, the latest one made before it started, permits it (definition below); $K = \bot$ while $W$ is open or either log is incomplete; $K = 0$ if any executed action is unmatched |
Evaluation is three-valued: each part is $1$, $0$ or $\bot$ (unknown). The outcome is:
- allow only if every part is $1$;
- deny if $H \in \{0, \bot\}$, or if $A = 0$, or if a coverage violation (below) is recorded and the holder has not yet cleared it. A never or unlisted action is a hard deny: no holder or approver can release it, so it is never turned into a hold;
- hold for the holder (wait for a person) in every other case, that is any remaining $0$ or $\bot$, including $A = \bot$ for a pending approval and $K = \bot$ for "cannot count yet".
Coverage, defined on action identities. Let $L_x$ be the build's own execution log and $L_d$ the gate's decision log, both keyed by action ID. A window $W$ is closed when its end has passed and every action that started in $W$ has its entry in $L_x$. Let $X_W$ be the actions in $L_x$ that started in $W$.
One action ID can collect several decisions: a hold and then an allow, an allow and then a revocation, a constraint and then a tighter one. The log keeps them all, but only one is in force when $x$ starts. The gate stamps each entry in $L_d$ with a sequence number $\sigma(d)$ that strictly increases across the whole log; $L_d$ is append-only, so a revocation or a changed constraint is a new entry, never an edit. The effective decision for $x$ is
e(x) = \operatorname*{arg\,max}_{\sigma} \{\, d \in L_d : \mathrm{id}(d) = \mathrm{id}(x),\ t(d) < t_{\text{start}}(x) \,\},the latest decision for that ID made before $x$ started. Earlier decisions for the same ID are superseded: they stay in the log as history and never count as current permission. An executed action $x \in X_W$ is matched if $e(x)$ exists, its outcome is allow or constrain, and $x$ is inside the constraints of $e(x)$. If two entries for one ID share a sequence number, or $\sigma$ disagrees with the timestamps, the order cannot be established and $L_d$ counts as incomplete for $W$. Report coverage as
c(W) = \frac{|\{x \in X_W : x \text{ matched}\}|}{|X_W|}, \quad \text{written "}m\text{ of }n\text{"}.Then $K = \bot$ if $W$ is not closed or either log is incomplete for $W$; $K = 1$ if every $x \in X_W$ is matched; otherwise $K = 0$. Proposals the gate denied or held have no entry in $X_W$, so they neither raise nor lower $c(W)$. An executed action whose effective decision is deny or hold, or that falls outside the constraints of its effective decision, is unmatched, and is also a coverage violation: a separate breach that triggers the stop until the holder decides. An empty $X_W$ with complete logs gives $K = 1$, reported "0 of 0: nothing ran". That says nothing ran unchecked; it is not evidence that the gate works.
Two checks against the old aggregate test ($n_{\text{seen}} = n_{\text{taken}}$), which this definition replaces. (i) The gate denies proposals $p_1, p_2$; the build executes $x_3, x_4$ with no decision. Totals are $2 = 2$, but $c(W) = $ 0 of 2 and $K = 0$. (ii) The gate allows $x_1$, which runs, and denies $p_2$, which does not. Totals are $2 \neq 1$, but $c(W) = $ 1 of 1 and $K = 1$.
Three checks on the effective-decision rule, all synthetic. (iii) Allow then revoke: $x_1$ is allowed at $\sigma = 1$ and denied at $\sigma = 2$, then executes. $e(x_1)$ is the deny, so $x_1$ is unmatched, $c(W) = $ 0 of 1, $K = 0$, and a coverage violation is recorded. Matching any earlier allow would wrongly give 1 of 1. (iv) Narrowed constraint: $x_1$ is constrained to amounts $\le 1000$ at $\sigma = 1$, tightened to $\le 100$ at $\sigma = 2$, then executes for 500. It is outside $e(x_1)$, so it is unmatched and a violation. (v) Hold then allow: $x_1$ is held at $\sigma = 1$ and allowed at $\sigma = 2$, then executes. $e(x_1)$ is the allow, so $x_1$ is matched and the earlier hold is not a violation.
Reporting "cannot count yet" is required honesty; it is not a pass. Under the course's all-eight rule, unestablished coverage holds the build. Relaxing that, so that unknown coverage permits unattended running, would be a policy change for the course leads, not a reading of this table.
Check the predicate against the procurement YAML below. Take $a = \texttt{pay}$, listed as {mode: never}, with every other part $1$. Then $m(a) = \text{never}$, so $A = 0$ and $G(a) = 0$, and the outcome is deny, not hold. Take an unlisted $a = \texttt{delete\_supplier}$: same result. Take $a = \texttt{submit\_po}$ before Priya Shah has decided: $A = \bot$, outcome hold; after her recorded yes for that order, $A = 1$.
A track row's "parts most at risk" is the subset $P \subset \{H,\dots,K\}$ its author judges most likely to be $0$ or $\bot$ for that build. It directs testing effort. It never replaces evaluating the other parts.
The three Level 300 cases each motivate one part:
- $O$. The Hong Kong Government reported a case received in end-January 2024 in which deepfakes were used to fabricate a pre-recorded video conference impersonating a Chief Financial Officer; transfers went to five local bank accounts, with a loss of about HK$200 million.6 The record does not name the organization; nor does this course.
- $B$ and $J$. A complaint filed 24 July 2023 alleges that over two months in 2022 Cigna doctors denied over 300,000 payment requests relying on an algorithm known as PXDX, spending "an average of just 1.2 seconds" on each; it cites news reporting for the figures.7 These are allegations; the case's later course is not checked. The course does not derive rates from them; budget arithmetic uses the synthetic log. A short recorded decision time is a signal to investigate, not a test of $J$ by itself: signing time is not total review time, and a mean over many decisions does not fix any single one. Evaluate $J$ on what the reviewer saw and whether they could disagree.
- $J$. A complaint filed 14 November 2023 alleges that UnitedHealth used the nH Predict model to override treating physicians' determinations, and that the model has a 90% error rate.8 These are allegations. The gate $J$ is the course's rule and holds regardless of the case's outcome.
4. The eleven tracks as specifications
Each row gives $k$, the scope of $C$ or $T$, the holder (fictional), and $P$.
| Track | $k$ | $C$ or $T$ | Holder (fictional) | $P$ | Basis |
|---|---|---|---|---|---|
| Makers and citizen developers | retrieval | Published plant safety procedures; no-answer response specified | Dana Okafor, plant safety lead | $A$ (read only), $K$, $H$ (collection kept current) | LLM082; 300.2-c |
| IT admins | agent | draft_ticket, read_directory; grant_access = approver; admin_* = never | Raj Mehta, identity service owner | $A$, $S$, $R$ (agent's own identity) | LLM063; 300.4-c |
| Early developers | retrieval | Engineering docs, per-document ACL at query time | Mei Lin, product owner | $A$, $R$, $K$ | LLM022; 300.2-a |
| Cybersecurity | agent | read_reported_mail, set_label; send, forward, delete = never | Tomás Silva, security operations lead | $A$, $S$ | LLM014; 300.6-c |
| Quality | retrieval | Warranty-claim notes (references, not customer data) | Grace Adeyemi, quality manager | $J$, $K$ | nH Predict allegations8; 300.5 |
| Engineering and design | retrieval | Released specifications only, with revision | Hana Ito, document control lead | $A$, $J$, $H$ | 300.2-c |
| Supply chain and procurement | agent | draft_po alone under limit; submit_po = approver; change_bank_details, pay = never | Priya Shah, procurement category manager | $A$, $O$, $B$ | Hong Kong record6; 300.4 |
| Customer service | agent | triage_claim, flag_for_review; deny_claim = approver | Luca Romano, warranty service manager | $B$, $J$, $R$ | Cigna allegations7; 300.8-b, 300.8-c |
| Finance | agent | match_invoice, flag_exception; pay, change_bank_details = never | Aisha Bello, accounts payable lead | $A$, $O$, $B$ | Hong Kong record6; 300.4-b |
| HR | retrieval | Published HR handbook only; personnel files excluded | Sofia Novak, HR policy owner | $A$, $H$; applicant screening out of scope | AI Act high-risk employment uses5; 300.7 |
| Legal | retrieval | Contract library, matter-level ACL | Daniel Cho, legal operations lead | $A$, $J$ | AI Act roles and transparency5; 300.7 |
A sketch of the procurement row's authority table, as the sandbox agent would read it (fictional; the course's sandbox fixtures are synthetic and not built yet):
build: procurement-po-drafter
holder: {name: "Priya Shah", role: procurement category manager, expires: 2027-03-31}
agent_identity: svc-po-drafter        # its own identity; never a person's login
default: deny                         # anything unlisted is denied
actions:
  draft_po:            {mode: alone, effects: [write], limit_eur: 5000}
  submit_po:           {mode: approver, approver: "Priya Shah", effects: [write, disclose]}
  change_bank_details: {mode: never}  # hard deny; done by people, out-of-band, outside the agent
  pay:                 {mode: never}  # hard deny; listing it does not authorize it
budget: {per_hour_system: 40}
stop: {on_missing: [holder, approval, record], action: deny}
receipt: [action, holder_ref, approval_ref, result, undo_ref]   # references only
On the HR row: the European Commission lists AI tools for employment, management of workers and access to self-employment, such as CV-sorting software for recruitment, as high-risk uses, and lists logging of activity and appropriate human oversight among the obligations for high-risk systems.5 As of 18 November 2026 its page says the rules for Annex III high-risk use cases will apply from 2 December 2027.5 Module 300.7 teaches checking such dates against the amending regulation in force. On the legal and customer-service rows: the Commission says that when using AI systems such as chatbots, humans should be made aware they are interacting with a machine.5
5. Exercise (bring to 300.P)
- Specify $b = (k, C, T, E)$ for one build in your role, or take a row above.
- Give $h(b) = (p, t_{\text{exp}})$. If no $p$ exists, $H = 0$ and the build is denied; record whom you will ask.
- Evaluate all eight parts as $1$, $0$ or $\bot$, and name $P$ with a reason for each member. For each $\bot$, name who can resolve it.
- Name the OWASP risk most likely for $b$2 and one control on $E$ that holds if the model is steered.
- For one other track, name any shared element of $C$ or $E$ with your build (data you own, decisions you make), and who you would notify. If the intersection is empty, say so and why.
Use synthetic data only. Do not paste real documents, logs, prompts or personal data. In real use, any prompt and output notes your workplace permits live in its own controlled work record, separate from the receipt. At 300.P a person reviews the specification; an AI does not.
6. Prep rails
A prep rail is a mapping $r: O \to X$ from a subset of course objectives $O$ to the published topic list $X$ of a vendor-proctored certification exam, with drills and mock items written by the course. Level 300 defines two:
| Rail | Vendor | Exam | Domain of $r$ |
|---|---|---|---|
| 1 | not cleared | not cleared | objectives of 300.1 to 300.6 |
| 2 | not cleared | not cleared | objectives of 300.6 to 300.9 |
As of 18 November 2026 both are "not cleared": Bob Rapp clears each vendor name before it appears.
The rail's outputs are coverage of $X$ by $O$ and a learner's practice results. The following do not follow from completing a rail (course rules):
- certification, which is issued only by the vendor on its own proctored exam, booked and sat by the learner;
- any act by the Foundation of sitting, granting or endorsing that exam;
- access to live exam content: the rail's items are the course's own;
- vendor endorsement of the course: no logos, no wording implying one.
A person reviews the Level 300 project and a host marks it; no model marks it. If earned, the Level 300 badge attests completion of this level and its project. It describes a person's practice, never a system's assurance, and it is not an instance of any vendor credential.
The Foundation applies the same boundary to outside university learning: its courses page says the listed programs are not degrees, that "none of them gives credit or a certificate through us", and that no university designed or endorses them.9 That page is about university courses, not vendor exams; each cleared vendor's own exam rules will need that vendor's own page.
7. Limits of this gear
- The Cigna and nH Predict figures are allegations in complaints, not findings, and are not used as inputs to any calculation.78 The cases' later course and outcomes are not checked.
- The Hong Kong organization is not named.6
- The track rows are illustrative specifications, not evaluated systems. No row's gate has been run. $G(a) = 1$ is the course's condition for unattended running, not a proof of safety or lawfulness.
- The AI Act dates are those on the Commission's page on 18 November 2026; this is not legal advice.5
- No vendor, exam or pass rate is named or implied.
Further learning
Deferred. Outside course pages can carry commercial platform, vendor and certification branding, and Level 300 vendor names wait for Bob Rapp's clearance. Until a destination is cleared, the cited sources are the reading list.